Semi-Supervised Learning
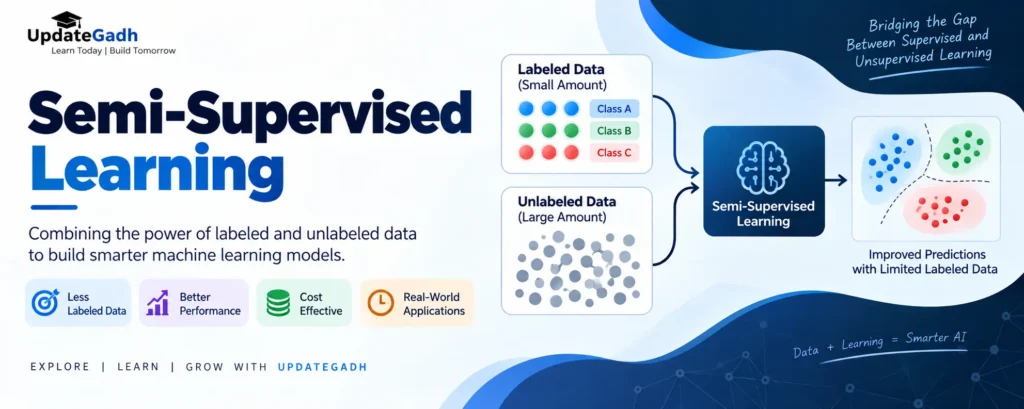
In the evolving field of machine learning, Semi-Supervised Learning (SSL) is a powerful approach that bridges the gap between Supervised Learning and Unsupervised Learning. It combines a small amount of labeled data with a much larger collection of unlabeled data, making it a practical and cost-effective solution for many real-world machine learning problems.
Table of Contents
Complete Advance AI Topics: Click Here
SQL Tutorial: Click Here
Understanding the Foundations
To understand the importance of Semi-Supervised Learning, it is helpful to first look at the major categories of machine learning:
- Supervised Learning: Uses labeled data where each input is associated with a known and correct output. It is similar to a student learning with continuous guidance from a teacher.
- Unsupervised Learning: Works with completely unlabeled data and attempts to discover hidden patterns, structures, or relationships without predefined outputs.
- Reinforcement Learning: Learns through trial and error by interacting with an environment and receiving rewards or penalties based on actions.
Semi-Supervised Learning finds a middle ground between supervised and unsupervised approaches. It uses a small amount of labeled data to guide the learning process while taking advantage of a much larger amount of unlabeled data.
Why Semi-Supervised Learning?
Labeled data can be expensive and time-consuming to collect because it often requires manual annotation and domain expertise. In contrast, unlabeled data is generally much more abundant and easier to obtain.
Traditional supervised learning models may struggle when only a limited number of labeled examples are available, while unsupervised learning does not always produce the specific predictions or classifications required by an application.
Semi-Supervised Learning addresses this challenge by:
- Reducing dependence on labeled data
- Improving model performance by utilizing unlabeled data
- Reducing the cost and time associated with data preparation
Core Assumptions Behind Semi-Supervised Learning
Semi-Supervised Learning generally relies on several assumptions about the structure of the data.
1. Continuity Assumption
The continuity assumption suggests that data points that are close to one another in the input space are likely to have the same label. SSL can use this property to create smoother decision boundaries, particularly in areas where data points are densely distributed.
2. Cluster Assumption
The cluster assumption states that data points belonging to the same cluster are likely to have the same class label. Since unlabeled data often forms natural groups, SSL can use these structures to improve classification.
3. Manifold Assumption
The manifold assumption suggests that high-dimensional data may lie on a lower-dimensional structure called a manifold. Semi-Supervised Learning can exploit this structure to learn meaningful patterns without working directly across the entire high-dimensional input space.
How Does Semi-Supervised Learning Work?
A typical Semi-Supervised Learning process can involve the following steps:
- Initial Training: A model is initially trained using the available labeled dataset.
- Pseudo Labeling: The trained model predicts labels for some or all of the unlabeled data.
- Data Merging: High-confidence pseudo-labeled examples are combined with the original labeled dataset.
- Re-training: The model is trained again using the expanded dataset to improve its ability to generalize.
This process allows the model to benefit from information contained in unlabeled examples while requiring significantly fewer manually labeled samples.
Semi-Supervised Learning vs Reinforcement Learning
Semi-Supervised Learning and Reinforcement Learning are both important machine learning approaches, but they solve different types of problems.
- Semi-Supervised Learning: Focuses on improving predictions or classification by combining a limited amount of labeled data with a larger amount of unlabeled data.
- Reinforcement Learning: Focuses on decision-making through interactions with an environment, where an agent learns actions that maximize cumulative rewards over time.
Real-World Applications of Semi-Supervised Learning
Semi-Supervised Learning is used in a variety of applications where labeled data is difficult or expensive to obtain.
Speech Analysis
Labeling audio recordings can require significant human effort. SSL can help models learn useful patterns from a small collection of labeled audio clips while also utilizing large amounts of unlabeled speech data.
Web Content Classification
Manually labeling large volumes of web pages is impractical. Semi-Supervised Learning can help classify and organize web content by learning from a combination of labeled and unlabeled examples.
Protein and DNA Sequence Classification
Biological datasets often contain huge quantities of unlabeled sequences, while accurate labeling may require specialized expertise. SSL can help identify useful patterns in protein and DNA sequence data using limited labeled examples.
Text Document Classification
Applications such as sentiment analysis and topic classification often require labeled text for training. Semi-Supervised Learning can reduce the amount of manual annotation required by making use of large collections of unlabeled documents.
Download New Real Time Projects :- Click here
Conclusion
Semi-Supervised Learning is a practical and powerful machine learning approach, particularly when labeled data is limited but unlabeled data is available in large quantities. By intelligently combining both types of data, SSL can help develop effective machine learning models while reducing the effort and cost required for data labeling.
As businesses and researchers continue to explore new machine learning applications, Semi-Supervised Learning remains an important technique for building models in situations where obtaining large labeled datasets is challenging.
Keywords: semi supervised learning, semi supervised learning example, semi supervised learning algorithms, semi supervised learning diagram, reinforcement learning, semi supervised learning applications, disadvantages of semi supervised learning, semi supervised learning algorithms list, semi supervised learning models, semi supervised learning types, self supervised learning, semi supervised learning in deep learning,