Dropout in Neural Networks
One of the major challenges in deep learning is building models that not only perform well on training data but also generalize effectively to unseen data. A common problem is overfitting, where a neural network achieves very high accuracy on training data but performs poorly on validation or test data.
To reduce overfitting, several regularization techniques are used in deep learning. Dropout is one of the most popular and effective techniques for improving the generalization ability of neural networks.
Complete Advance AI Topics: Click Here
SQL Tutorial: Click Here
What is Dropout?
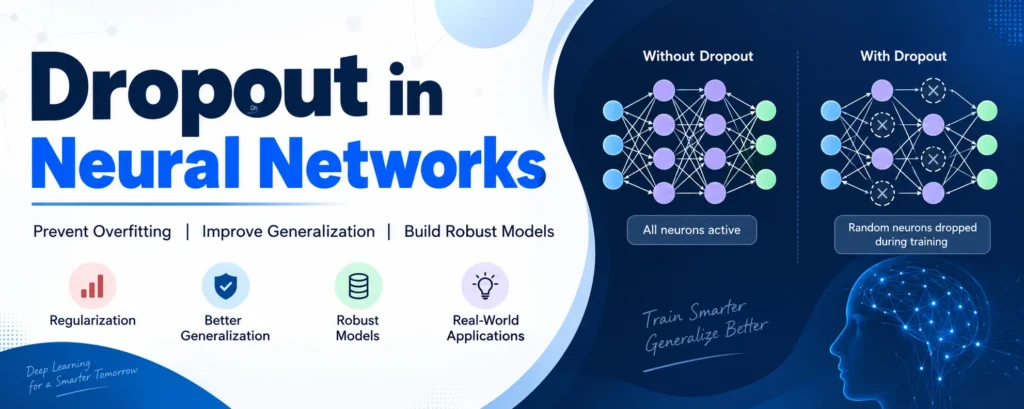
Dropout is a regularization technique used in neural networks to reduce overfitting. During training, dropout randomly disables a percentage of neurons in a layer.
At every training iteration, a different set of neurons may be dropped. This prevents the network from becoming overly dependent on particular neurons or features and encourages it to learn more distributed and robust representations.
During inference or testing, dropout is disabled. The network uses all neurons, with appropriate scaling applied during training so that the expected activations remain consistent between training and inference.
How Does Dropout Work?
Suppose a neural network contains 10 neurons in a hidden layer and the dropout rate is set to 0.5. During a particular training iteration, approximately half of those neurons may be temporarily disabled.
In the next iteration, a different group of neurons can be disabled. As a result, the network effectively trains many different subnetworks instead of relying on a single fixed configuration.
This encourages the model to learn features that are useful independently rather than depending too heavily on individual neurons.
Benefits of Dropout in Neural Networks
1. Prevents Overfitting
The primary purpose of dropout is to reduce overfitting. By randomly disabling neurons during training, dropout prevents the network from becoming overly dependent on specific features or neuron combinations.
2. Improves Model Robustness
Because the model must continue learning even when some neurons are unavailable, it develops more distributed representations. This can make the resulting model more robust to variations in input data.
3. Acts as a Regularizer
Dropout adds noise to the training process by randomly removing activations. This acts as a form of regularization and can help control model complexity.
4. Provides an Ensemble-Like Effect
Dropout can be viewed as training many different subnetworks that share parameters. This creates an effect somewhat similar to model averaging or ensemble learning without requiring completely separate models to be trained.
5. Improves Generalization
By reducing the model’s dependence on specific neurons, dropout can help improve performance on validation and test data, particularly when the network has enough capacity to overfit.
Choosing the Right Dropout Rate
The dropout rate determines the proportion of activations that are randomly dropped during training.
Common dropout rates include 0.2, 0.3, and 0.5. A rate of 0.5 means that approximately half of the activations are dropped during each training step for that layer.
The ideal value depends on the dataset, architecture, and other regularization techniques being used.
- Lower dropout rate: Keeps more information but may provide weaker regularization.
- Higher dropout rate: Provides stronger regularization but can make learning difficult and potentially cause underfitting.
Therefore, the dropout rate should generally be selected through experimentation and validation rather than using one fixed value for every neural network.
Dropout Variants
Several variations of dropout have been developed for different neural network architectures and use cases.
- Spatial Dropout: Commonly used with convolutional neural networks. Instead of independently dropping individual elements, it can drop entire feature maps or channels.
- DropConnect: Randomly removes connections or weights rather than directly dropping neuron activations.
- AlphaDropout: Designed to work with SELU activation functions while helping preserve the statistical properties required by self-normalizing networks.
- Variational Dropout: Uses a probabilistic approach to dropout and can learn different dropout behavior for different parameters.
- Monte Carlo Dropout: Keeps dropout active during prediction and can be used to estimate predictive uncertainty.
- Concrete Dropout: Uses a differentiable formulation that allows dropout probabilities to be learned during training.
- Gaussian Dropout: Uses multiplicative Gaussian noise as a regularization mechanism.
Dropout in Neural Networks
Dropout is usually added between layers of a neural network. For example, a fully connected network can contain a Dense layer followed by a Dropout layer.
A simplified architecture might look like this:
Input
  ↓
Dense Layer
  ↓
Dropout
  ↓
Dense Layer
  ↓
Dropout
  ↓
Output Layer
During training, the Dropout layers randomly deactivate activations. During inference, dropout is automatically disabled and the complete network is used.
Implementation of Dropout in TensorFlow/Keras
Let’s see how dropout can be used with the MNIST dataset using TensorFlow and Keras. We will compare two neural networks: one without dropout and another with dropout.
Step 1: Import Required Libraries
import numpy as np
import matplotlib.pyplot as plt
import tensorflow as tf

from tensorflow.keras.models import Sequential
from tensorflow.keras.layers import Dense, Dropout
from tensorflow.keras.datasets import mnist
from tensorflow.keras.utils import to_categorical
Step 2: Load and Preprocess the Data
The MNIST dataset contains handwritten digit images. Each image has a size of 28 × 28 pixels. We flatten each image into a vector of 784 values and normalize the pixel values between 0 and 1.
(train_X, train_y), (test_X, test_y) = mnist.load_data()

train_X = train_X.reshape(-1, 28 * 28).astype('float32') / 255
test_X = test_X.reshape(-1, 28 * 28).astype('float32') / 255

train_y = to_categorical(train_y, 10)
test_y = to_categorical(test_y, 10)
Step 3: Build a Model Without Dropout
First, we create a neural network without dropout. This model contains two hidden layers with 512 neurons each.
model_no_dropout = Sequential([
    Dense(512, activation='relu', input_shape=(784,)),
    Dense(512, activation='relu'),
    Dense(10, activation='softmax')
])

model_no_dropout.compile(
    optimizer='adam',
    loss='categorical_crossentropy',
    metrics=['accuracy']
)

history_no_dropout = model_no_dropout.fit(
    train_X,
    train_y,
    epochs=20,
    batch_size=128,
    validation_split=0.2,
    verbose=2
)
Step 4: Build a Model With Dropout
Next, we add Dropout layers after the hidden Dense layers. Here, the dropout rate is set to 0.5.
model_with_dropout = Sequential([
    Dense(512, activation='relu', input_shape=(784,)),
    Dropout(0.5),
    Dense(512, activation='relu'),
    Dropout(0.5),
    Dense(10, activation='softmax')
])

model_with_dropout.compile(
    optimizer='adam',
    loss='categorical_crossentropy',
    metrics=['accuracy']
)

history_with_dropout = model_with_dropout.fit(
    train_X,
    train_y,
    epochs=20,
    batch_size=128,
    validation_split=0.2,
    verbose=2
)
Visualizing Model Performance
Accuracy Comparison
We can compare the training and validation accuracy of both models using Matplotlib.
plt.figure(figsize=(14, 6))

plt.subplot(1, 2, 1)
plt.plot(history_no_dropout.history['accuracy'], label='Train')
plt.plot(history_no_dropout.history['val_accuracy'], label='Validation')
plt.title('Accuracy without Dropout')
plt.xlabel('Epoch')
plt.ylabel('Accuracy')
plt.legend()

plt.subplot(1, 2, 2)
plt.plot(history_with_dropout.history['accuracy'], label='Train')
plt.plot(history_with_dropout.history['val_accuracy'], label='Validation')
plt.title('Accuracy with Dropout')
plt.xlabel('Epoch')
plt.ylabel('Accuracy')
plt.legend()

plt.show()
Combined Accuracy Plot
plt.figure(figsize=(14, 6))

plt.plot(
    history_no_dropout.history['accuracy'],
    label='Train without Dropout'
)

plt.plot(
    history_no_dropout.history['val_accuracy'],
    label='Validation without Dropout'
)

plt.plot(
    history_with_dropout.history['accuracy'],
    label='Train with Dropout'
)

plt.plot(
    history_with_dropout.history['val_accuracy'],
    label='Validation with Dropout'
)

plt.title('Dropout vs No Dropout Accuracy')
plt.xlabel('Epoch')
plt.ylabel('Accuracy')
plt.legend()

plt.show()
Loss Comparison
Loss curves can also help us understand how the two models behave during training.
plt.figure(figsize=(14, 6))

plt.subplot(1, 2, 1)
plt.plot(history_no_dropout.history['loss'], label='Train')
plt.plot(history_no_dropout.history['val_loss'], label='Validation')
plt.title('Loss without Dropout')
plt.xlabel('Epoch')
plt.ylabel('Loss')
plt.legend()

plt.subplot(1, 2, 2)
plt.plot(history_with_dropout.history['loss'], label='Train')
plt.plot(history_with_dropout.history['val_loss'], label='Validation')
plt.title('Loss with Dropout')
plt.xlabel('Epoch')
plt.ylabel('Loss')
plt.legend()

plt.show()
Dropout During Training vs Inference
It is important to understand that dropout behaves differently during training and inference.
| Phase | Dropout Behavior |
|---|---|
| Training | Randomly drops activations according to the specified dropout rate. |
| Inference | Dropout is disabled and the complete network is used. |
Modern deep learning frameworks such as TensorFlow/Keras handle this training and inference behavior automatically when the model is used correctly.
YT:- DecodeIT
Dropout in CNNs
Dropout can also be used in Convolutional Neural Networks (CNNs), particularly in fully connected portions of the network. For convolutional feature maps, techniques such as spatial dropout can sometimes be more appropriate because neighboring activations can be highly correlated.
Dropout vs Batch Normalization
Dropout and batch normalization serve different purposes. Dropout primarily acts as a regularization technique by randomly removing activations during training, while batch normalization normalizes intermediate activations and can also have a regularizing effect.
Whether both should be used together depends on the architecture, dataset, and training behavior. They should not be treated as interchangeable techniques.
Conclusion
Dropout is a simple but powerful regularization technique for reducing overfitting in neural networks. By randomly disabling a portion of activations during training, it encourages the model to learn more distributed and robust representations.
Although dropout can cause training accuracy to improve more slowly, it can provide better generalization when a model is prone to overfitting. The appropriate dropout rate depends on the architecture and dataset, so it is important to evaluate different values using validation performance.
Dropout remains an important technique to understand when working with neural networks, deep learning, and other machine learning models.
Keywords
what is dropout in machine learning, what is dropout in deep learning, dropout in neural network, dropout regularization in deep learning, dropout layer, dropout rate neural network, dropout in CNN, dropout in neural network Python, dropout in neural network PyTorch, purpose of dropout in neural network, how to implement dropout in neural network, dropout neural network example, dropout vs batch normalization, dropout during training, dropout during inference, TensorFlow dropout, Keras dropout, neural network regularization, preventing overfitting with dropout