Matrix Decomposition in Machine Learning
In machine learning, data is often represented in the form of matrices. As datasets become larger and more complex, working directly with these matrices can become computationally expensive. Matrix decomposition provides an effective way to simplify these matrices into smaller or more manageable components.
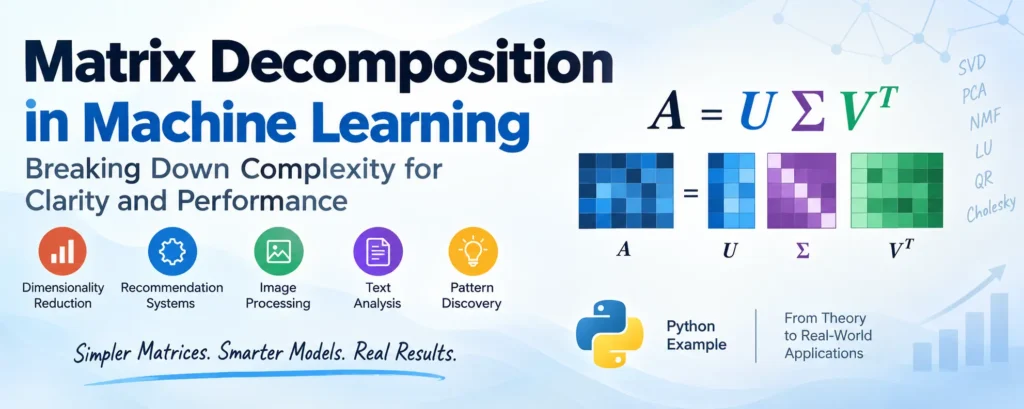
Matrix decomposition, also called matrix factorization, is useful in areas such as dimensionality reduction, recommendation systems, image processing, text analysis, and pattern discovery. By breaking complex matrices into simpler matrices, machine learning algorithms can process data more efficiently while revealing important hidden structures.
Table of Contents
Complete Advance AI Topics: Click Here
SQL Tutorial: Click Here
What Is Matrix Decomposition?
Matrix decomposition is the process of breaking a matrix into two or more simpler matrices. When these component matrices are multiplied together, they can reconstruct the original matrix or provide a close approximation of it.
For example, a matrix can be represented using different decomposition techniques depending on its properties and the problem being solved.
Matrix decomposition can help to:
- Reduce computational complexity.
- Discover hidden patterns and structures in data.
- Reduce the dimensionality of datasets.
- Improve the efficiency of machine learning algorithms.
- Simplify mathematical operations involving large matrices.
Types of Matrix Decomposition
Different decomposition techniques are suitable for different types of matrices and machine learning problems.
| Decomposition | Main Use | Key Characteristic |
|---|---|---|
| SVD | Dimensionality reduction, recommender systems | Works with general matrices |
| Eigenvalue Decomposition | PCA and mathematical analysis | Generally used with square matrices |
| LU Decomposition | Linear equations and numerical computing | Uses lower and upper triangular matrices |
| QR Decomposition | Least squares and eigenvalue problems | Numerically stable |
| Cholesky Decomposition | Optimization and probabilistic models | Requires positive-definite matrices |
| NMF | Topic modeling and pattern discovery | Produces non-negative components |
1. Singular Value Decomposition (SVD)
Singular Value Decomposition (SVD) decomposes a matrix into three matrices:
A = UΣVᵀ
Here:
Ucontains the left singular vectors.Σis a diagonal matrix containing singular values.Vᵀcontains the right singular vectors.
SVD is widely used for:
- Dimensionality reduction.
- Principal Component Analysis (PCA).
- Recommender systems.
- Image compression.
- Noise reduction.
One of its major advantages is that it can identify the most important components of data while allowing less important information to be discarded.
2. Eigenvalue Decomposition
Eigenvalue decomposition represents a suitable square matrix using its eigenvectors and eigenvalues.
It is commonly associated with:
- Principal Component Analysis (PCA).
- System stability analysis.
- Mathematical and scientific computing.
- Solving certain differential equation problems.
Unlike SVD, eigenvalue decomposition is generally restricted to square matrices and requires suitable properties for the decomposition to exist in the desired form.
3. LU Decomposition
LU Decomposition separates a matrix into a lower triangular matrix L and an upper triangular matrix U.
A = LU
It is commonly used for:
- Solving systems of linear equations.
- Matrix calculations.
- Determinant-related calculations.
- Numerical and scientific computing.
LU decomposition can make repeated solutions of linear systems more efficient because the matrix can be factored once and then reused.
4. QR Decomposition
QR Decomposition factors a matrix into an orthogonal matrix Q and an upper triangular matrix R.
A = QR
It is particularly useful for:
- Least squares regression.
- Orthogonalization of vectors.
- Solving eigenvalue problems.
- Numerical linear algebra.
QR decomposition is also useful for non-square matrices and is known for its numerical stability.
5. Cholesky Decomposition
Cholesky Decomposition is designed for symmetric positive-definite matrices. It decomposes a matrix into a lower triangular matrix and its transpose.
A = LLᵀ
It is used in areas such as:
- Gaussian Processes.
- Kalman filters.
- Optimization algorithms.
- Numerical computations.
The main limitation is that the matrix must satisfy the required positive-definite conditions.
6. Non-negative Matrix Factorization (NMF)
Non-negative Matrix Factorization (NMF) decomposes a non-negative matrix into smaller matrices whose elements are also non-negative.
This property can make the resulting components easier to interpret.
NMF is commonly used for:
- Text clustering.
- Topic modeling.
- Image processing.
- Audio signal analysis.
- Pattern discovery.
Because negative values are not introduced into the factorized matrices, NMF can be particularly useful when the original data naturally contains non-negative values.
Practical Example: News Article Classification Using NMF
Let’s use Non-negative Matrix Factorization (NMF) with TF-IDF features to discover topics in BBC news articles.
Step 1: Import Libraries
import numpy as np
import pandas as pd
import re
import nltk

from nltk.corpus import stopwords
from nltk.tokenize import word_tokenize
from sklearn.feature_extraction.text import TfidfVectorizer
from sklearn.decomposition import NMF
Step 2: Load and Explore the Dataset
train = pd.read_csv('/kaggle/input/learn-ai-bbc/BBC News Train.csv')

print(train.head())
print(train['Category'].value_counts())
The dataset contains news articles along with their categories. Examining the dataset first helps us understand the available text and category distribution.
Step 3: Clean the Text
Before converting the articles into numerical features, the text needs to be cleaned.
stop_words = set(stopwords.words('english'))

def clean_text(text):
    text = re.sub(r'[^a-zA-Z\s]', '', text)
    tokens = word_tokenize(text.lower())
    tokens = [word for word in tokens if word not in stop_words]
    return ' '.join(tokens)

train['clean_text'] = train['Text'].apply(clean_text)
This process removes unwanted characters, converts text to lowercase, tokenizes the content, and removes common English stopwords.
Step 4: Convert Text into TF-IDF Features
NMF works with numerical matrices, so the cleaned articles are converted into a TF-IDF matrix.
vectorizer = TfidfVectorizer(max_features=1000)

X = vectorizer.fit_transform(train['clean_text'])
The resulting matrix represents the importance of words across the news articles.
Step 5: Apply NMF
Now we can apply Non-negative Matrix Factorization.
nmf_model = NMF(
    n_components=5,
    random_state=42
)

W = nmf_model.fit_transform(X)
H = nmf_model.components_
Here, n_components=5 asks NMF to identify five underlying topics.
Step 6: Analyze the Topics
We can examine the words that contribute most strongly to each topic.
feature_names = vectorizer.get_feature_names_out()

for topic_idx, topic in enumerate(H):
    top_words = [
        feature_names[i]
        for i in topic.argsort()[:-11:-1]
    ]

    print(f"Topic #{topic_idx}:")
    print(" ".join(top_words))
The most important words for each topic can give us an idea of what that topic represents. For example, a group of words related to teams, matches, and players may indicate a sports-related topic.
Why Matrix Decomposition Matters
Matrix decomposition helps make complex datasets easier to process and understand. Its applications extend across many areas of machine learning and data science.
Healthcare
Matrix decomposition can be used for analyzing complex datasets such as genomic information and medical data.
Finance
Financial models can use matrix-based techniques for areas such as risk analysis and fraud detection.
Retail
Recommendation systems can use matrix factorization techniques to discover relationships between users and products.
Natural Language Processing
Techniques such as NMF can help identify hidden topics and patterns within large collections of documents.
YT:- DecodeIT
Conclusion
Matrix decomposition is an important mathematical foundation of machine learning and data science. It provides a practical way to break complex matrices into simpler components, making large-scale computations easier and helping reveal hidden patterns within data.
Techniques such as SVD, Eigenvalue Decomposition, LU, QR, Cholesky, and NMF each have different strengths and applications.
Whether the goal is dimensionality reduction, image compression, recommendation systems, numerical computation, or topic modeling, choosing the appropriate matrix decomposition technique can make machine learning workflows more efficient and interpretable.
Keywords: matrix decomposition in machine learning, matrix decomposition example, matrix decomposition in machine learning Python, matrix factorization in machine learning, SVD in machine learning, NMF in machine learning, matrix factorization in recommender systems, matrix decomposition example Python