Softmax Activation Function
Machine Learning has become an important technology for solving complex problems across areas such as finance, healthcare, and artificial intelligence. It enables algorithms to learn from data and make predictions or decisions without requiring every situation to be explicitly programmed.
One of the most powerful components of modern machine learning is the neural network. Inspired by the structure of the human brain, neural networks consist of interconnected layers of neurons that perform mathematical transformations on input data. These layers gradually learn useful patterns and relationships, allowing the network to produce meaningful predictions.
Table of Contents
Complete Advance AI Topics: Click Here
SQL Tutorial: Click Here
Role of Activation Functions
An activation function is a key component of a neural network. It introduces non-linearity into the network, allowing the model to learn complex patterns instead of being limited to simple linear relationships.
The choice of an activation function can affect:
- How effectively the network learns during training.
- The convergence behavior of the model.
- How well the model generalizes to unseen data.
Popular activation functions include ReLU, Tanh, and Sigmoid. These functions influence neuron outputs and the gradients used during backpropagation to update weights and biases.
Complete Python Course with Advance Topics:
SQL Tutorial:
Data Science Tutorial:
Softmax Activation Function: A Deep Dive
The Softmax activation function is widely used in multi-class classification problems. It can be considered a generalization of the sigmoid function for situations involving more than two classes.
While sigmoid can produce a probability for a binary classification output, Softmax calculates probabilities for multiple classes simultaneously. The resulting probabilities add up to 1, making them useful for interpreting the output of a classification model.
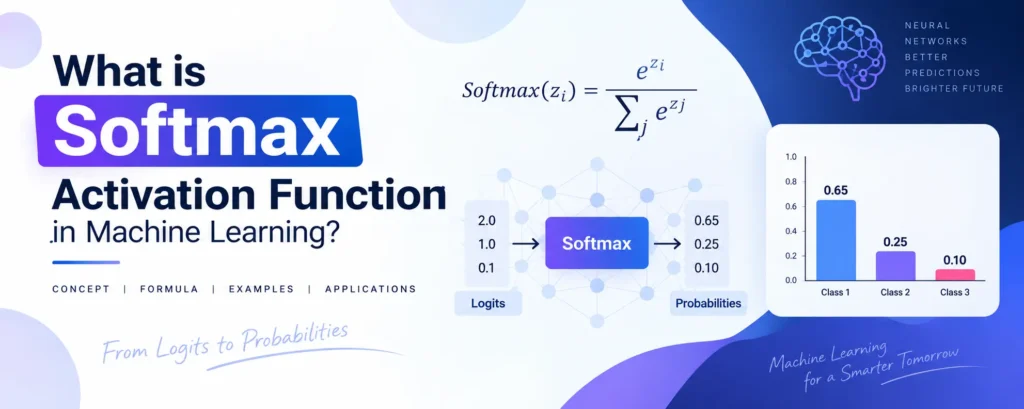
The raw outputs produced by the final layer of a neural network are called logits. Softmax converts these logits into a normalized probability distribution.
How Does Softmax Activation Work?
The Softmax function works mainly through two steps:
1. Exponentiation
Each logit is passed through the exponential function. This makes all resulting values positive and increases the differences between larger and smaller scores.
2. Normalization
Each exponentiated value is divided by the sum of all exponentiated logits. This ensures that all output probabilities add up to 1.
The Softmax formula is:
Softmax(zi) = ezi / Σj ezj
Here, zi represents the logit or raw score for class i.
Softmax Function Example
Suppose a neural network produces the following logits for three classes:
[2.0, 1.0, 0.1]After applying Softmax, these values can be converted into probabilities approximately like:
[0.66, 0.24, 0.10]The probabilities add up to approximately 1. The class with the highest probability is selected as the predicted class.
Why is Softmax Essential for Multi-Class Classification?
Neural networks often produce raw numerical scores that are difficult to interpret directly. Softmax converts these scores into probabilities, making the model’s prediction easier to understand.
Class Prediction
The class with the highest Softmax probability is generally selected as the predicted label.
Confidence Level
The probability associated with a class provides an indication of how strongly the model favors that class over the alternatives.
Probability-Based Decisions
Softmax outputs can be useful when an application needs to make decisions based on predicted probabilities, such as classification and risk-related predictions.
Advantages of the Softmax Activation Function
- Differentiable: Softmax is differentiable, making it suitable for gradient-based training and backpropagation.
- Handles Multiple Classes: It is particularly useful when an input belongs to one class among several possible classes.
- Probability Interpretation: Its outputs form a normalized probability distribution, making classification results easier to interpret.
Limitations of the Softmax Activation Function
- Computational Overhead: With a very large number of classes, calculating exponentials and normalization can become computationally expensive.
- Sensitivity to Large Logits: Very large differences between logits can cause one class to dominate the probability distribution.
- Mutually Exclusive Classes: Softmax is generally appropriate when classes are mutually exclusive. It is not the natural choice for multi-label problems where multiple classes can be correct simultaneously.
Implementing Softmax in Popular Frameworks
TensorFlow Example
import tensorflow as tf

# Define a simple neural network model
model = tf.keras.Sequential([
    tf.keras.layers.Dense(10, input_shape=(20,)),
    tf.keras.layers.Softmax()
])

# Compile the model
model.compile(
    optimizer='adam',
    loss='sparse_categorical_crossentropy',
    metrics=['accuracy']
)

# Generate a sample input
inputs = tf.random.uniform((1, 20))

# Get the model's prediction
predictions = model(inputs)

print(predictions.numpy())
In this example:
- A dense layer processes the input data.
- The Softmax layer converts the output into a probability distribution over 10 classes.
- The Adam optimizer is used for training.
- Sparse categorical crossentropy is used as the classification loss.
PyTorch Example
import torch
import torch.nn as nn

# Define a simple neural network
class SimpleNN(nn.Module):
    def __init__(self):
        super(SimpleNN, self).__init__()
        self.fc = nn.Linear(20, 10)

    def forward(self, x):
        x = self.fc(x)
        return torch.softmax(x, dim=1)

# Create the model instance
model = SimpleNN()

# Generate a sample input
inputs = torch.randn(1, 20)

# Get model predictions
predictions = model(inputs)

print(predictions)
In this PyTorch example:
- The model contains a fully connected linear layer.
- Softmax is applied across the class dimension using dim=1.
- The resulting values represent probabilities for the 10 classes.
- The probabilities across the classes sum to 1.
Download New Real-Time Projects: Click here
Softmax vs Sigmoid
| Feature | Softmax | Sigmoid |
|---|---|---|
| Typical Use | Multi-class classification | Binary classification |
| Output | Multiple class probabilities | Probability for an individual output |
| Probability Sum | Outputs generally sum to 1 | Outputs do not need to sum to 1 |
| Class Relationship | Best suited to mutually exclusive classes | Can be used independently for multiple labels |
Conclusion
The Softmax activation function is an important component of machine learning and neural network models, particularly for multi-class classification. It transforms raw logits into a normalized probability distribution, making model predictions easier to interpret.
Softmax is differentiable, supports multiple classes, and provides probability-based outputs that are useful for classification tasks. However, it can introduce computational overhead when dealing with a very large number of classes and is most suitable when the possible classes are mutually exclusive.
Understanding Softmax, along with related concepts such as Sigmoid, ReLU, and the Adam optimizer, provides a strong foundation for working with neural networks and modern machine learning models.
Keywords: softmax activation function in machine learning, softmax activation function in neural network, softmax function, softmax vs sigmoid, softmax function example, softmax activation function graph, softmax activation function formula, softmax function Python, softmax activation function in machine learning Python, softmax activation function GeeksforGeeks, ReLU activation function, Adam optimizer