
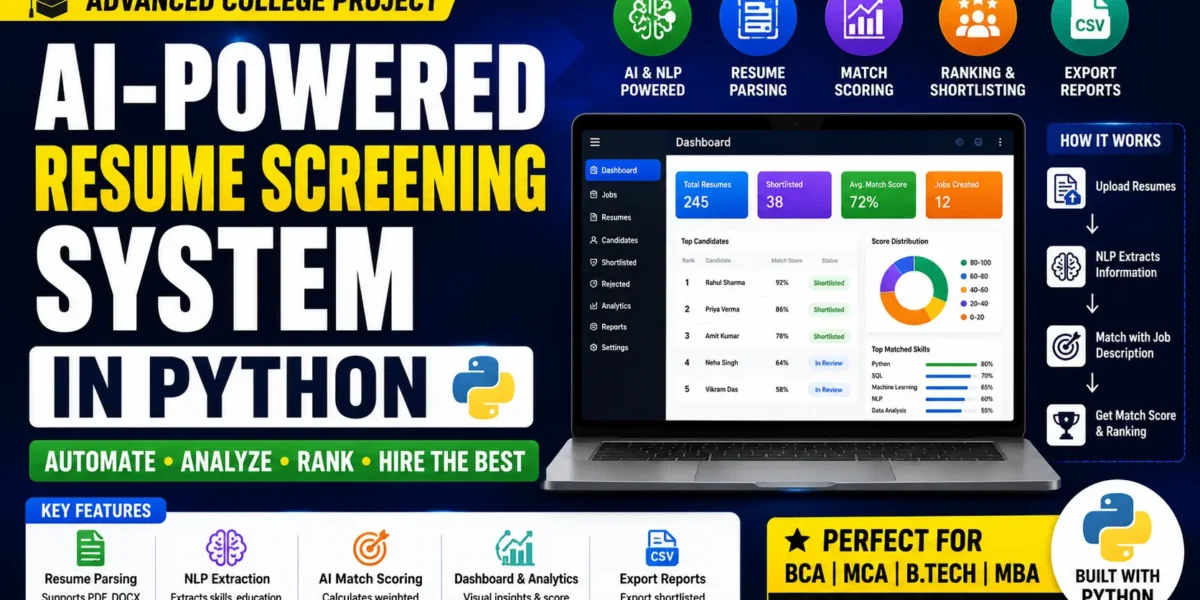
Looking for an AI Powered Resume Screening System in Python with full source code? This is one of the most impressive final year projects for MCA, BCA, B.Tech, and MBA students in 2026, targeting AI, Data Science, and HR-Tech roles. The system screens multiple resumes against a job description, extracts structured candidate information using NLP, and ranks every applicant by a weighted Job-Match Score percentage – complete with an interactive analytics dashboard, skill-gap charts, one-click shortlist or reject actions, and CSV/Excel export. In this post you get the complete source code, full feature breakdown, project structure, tech stack, and step-by-step setup guide.
Project Overview
| Project Name | AI Powered Resume Screening System with Job Match Score |
| Language Used | Python 3.x |
| Web Framework | Flask (application-factory pattern) |
| ORM | SQLAlchemy |
| AI / NLP | spaCy NER, scikit-learn TF-IDF, optional BERT (sentence-transformers) |
| File Parsing | PyMuPDF (fitz), python-docx |
| Frontend | HTML5, custom CSS design system, JavaScript, Chart.js |
| Database | SQLite (default) / MySQL (switchable) |
| Project Type | Web Application (HR-Tech / AI) |
| Difficulty | Advanced |
| Best For | MCA, BCA, B.Tech, MBA Final Year Students |
| Developer | Updategadh |
About the Project
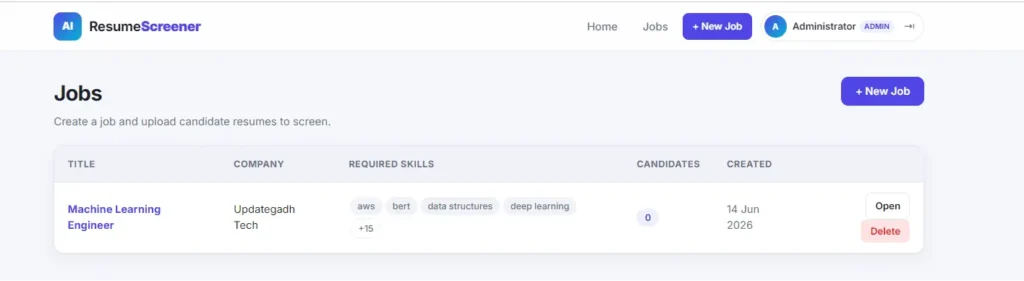
The AI Powered Resume Screening System is a full-stack HR automation tool built with Flask, spaCy, and scikit-learn that solves a real-world business problem – manually screening hundreds of resumes for a single job opening. Recruiters upload multiple resumes in PDF or DOCX format, define a job description with required skills, minimum experience, and education level, and the system parses every resume, extracts structured candidate information, and ranks applicants by a weighted Job-Match Score percentage.
Key Features
- Resume Parser: Extracts clean text from messy multi-format PDF and DOCX resumes using PyMuPDF and python-docx.
- NLP Extractor: Pulls out candidate name, email, phone, skills, education, and experience using spaCy Named Entity Recognition combined with regex patterns.
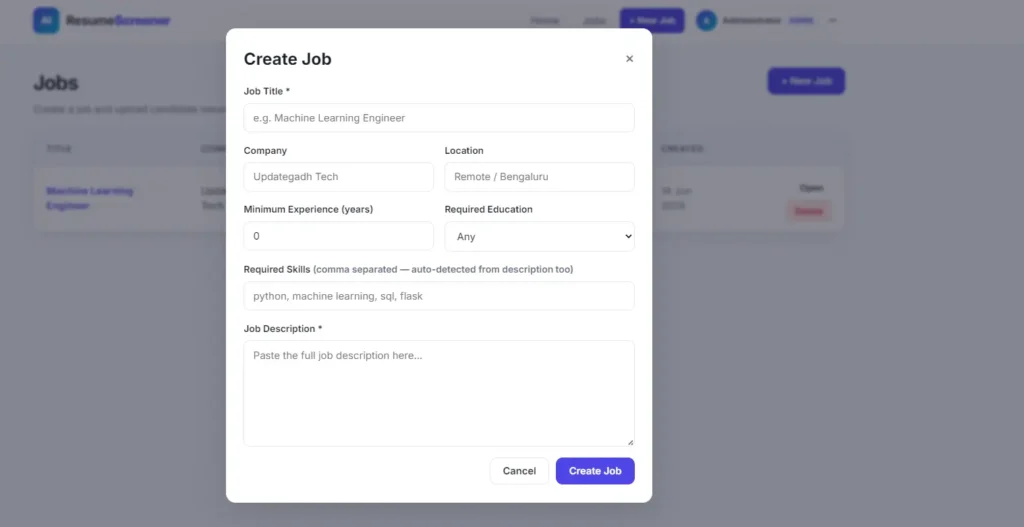
- Job Description Module: Create jobs with required skills, minimum years of experience, and education level – skills are auto-detected from the JD text.
- Weighted Match Engine: Scores every candidate across skills, experience, education, and semantic similarity using TF-IDF or optional BERT cosine similarity.
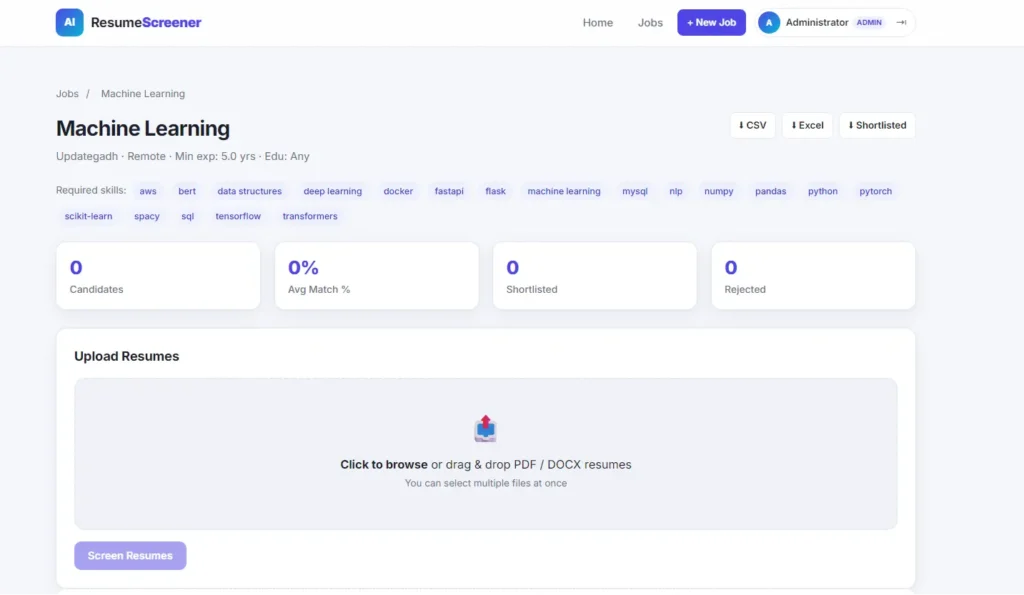
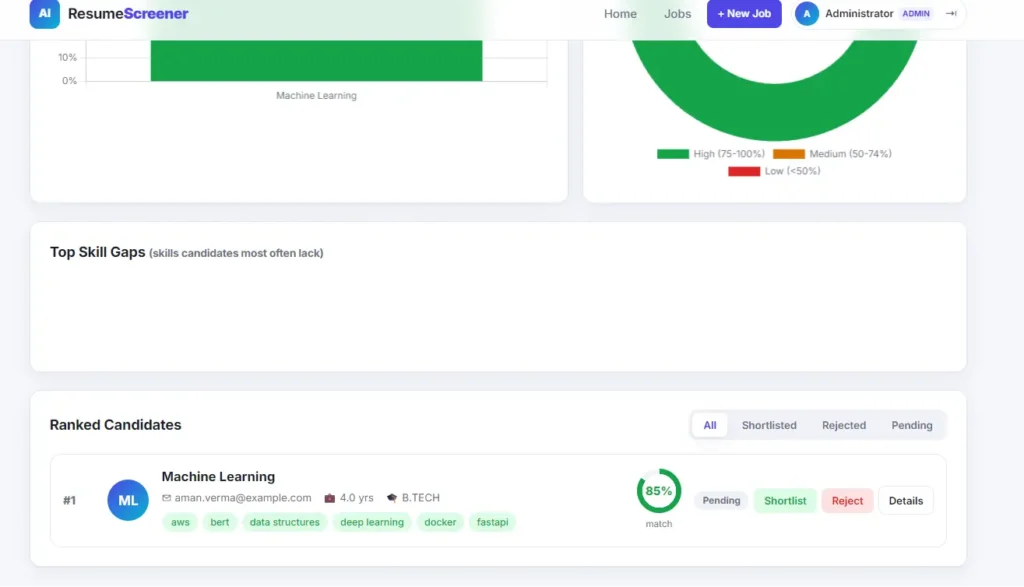
- Interactive Analytics Dashboard: Chart.js bar graphs, score distribution doughnut charts, and detailed skill-gap analysis per candidate.
- One-Click Shortlist / Reject: AJAX-powered status updates with live filtering of candidates.
- CSV and Excel Export: Download ranked or shortlisted candidates as CSV or Excel files using openpyxl.
- Pluggable Database: Works out of the box with SQLite, switches to MySQL with a single environment variable change.
- Configurable Score Weights: Adjust the weighting formula directly in the config file without touching core code.
- Unit Tested: Comes with pytest test cases for the core matching engine.
Technologies Used
| Layer | Technology |
| Backend | Python 3, Flask (application-factory pattern) |
| ORM | SQLAlchemy + Flask-Migrate |
| NLP | spaCy (en_core_web_sm) with NER |
| Machine Learning | scikit-learn TF-IDF, optional sentence-transformers BERT |
| Document Parsing | PyMuPDF (fitz), python-docx |
| Frontend | HTML5, custom CSS design system, JavaScript, Chart.js |
| Export | openpyxl (Excel), built-in csv module |
| Database | SQLite (default), MySQL (production-ready) |
| Testing | pytest |
Job Match Score Calculation
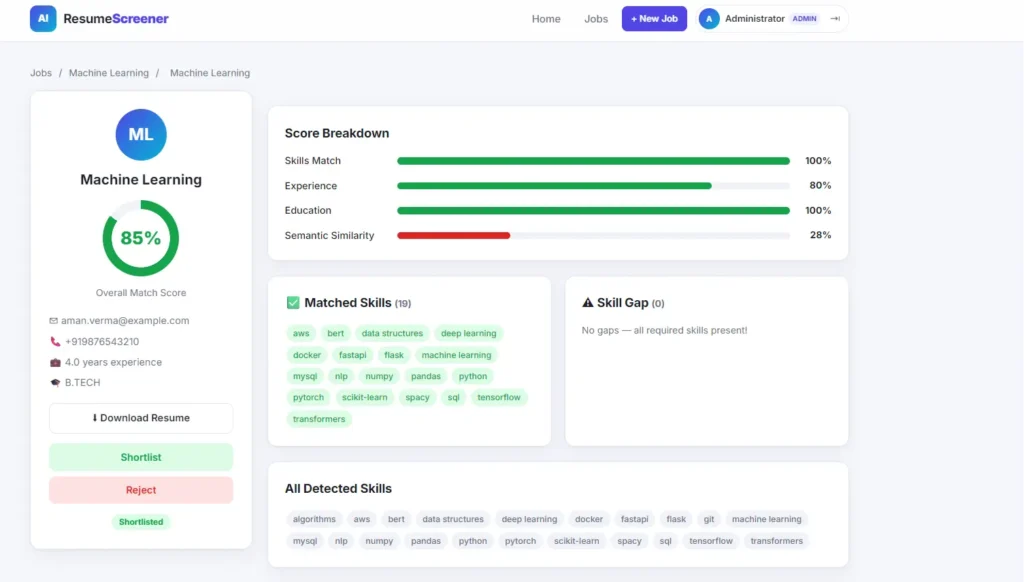
The match score is calculated using four weighted factors:
- Skills (50%): Matches resume skills with job requirements.
- Experience (20%): Compares candidate experience with required experience.
- Education (15%): Compares education levels.
- Semantic Similarity (15%): Measures contextual similarity between the resume and job description using TF-IDF or BERT.
All weights are configurable in app/config.py.
How to Run This Project
- Open Project Folder:
cd "Ai Powered-Resume-Analyzer" - Create Virtual Environment:
python -m venv venv venv\Scripts\activate - Install Dependencies:
pip install -r requirements.txt - Download spaCy Model:
python -m spacy download en_core_web_sm - Configure Environment:
copy .env.example .env - Seed Sample Data (Optional):
python seed.py - Run Application:
python run.py
Configuration
Update settings in the .env file:
| Variable | Default |
|---|---|
| DATABASE_URL | SQLite |
| MATCH_ENGINE | tfidf |
| SECRET_KEY | dev key |
| MAX_CONTENT_LENGTH_MB | 16 |
MySQL Setup: Create the resume_screening database and update DATABASE_URL with your MySQL connection string.
BERT Matching: Install sentence-transformers and set MATCH_ENGINE=bert in .env.
How to Download
The complete package is available so you can run, study, and submit it with confidence.
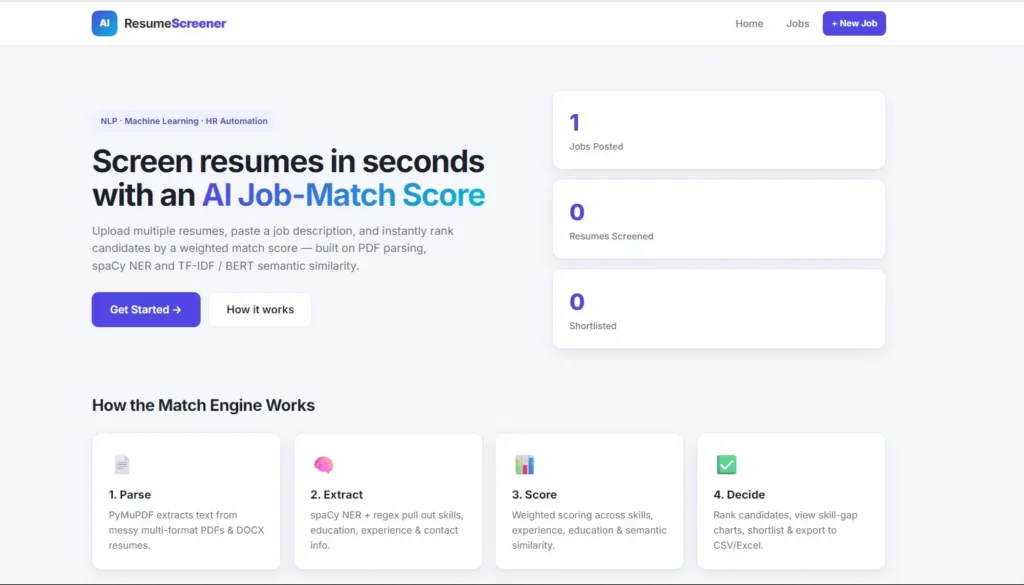
Screenshots
Why This Is a Great Final Year Project
- Real-world HR automation – solves an actual business problem, not a toy use case.
- Combines NLP + Machine Learning + Web Development – covers three trending domains in one project.
- spaCy NER and TF-IDF cosine similarity – directly relevant to AI and Data Science placements.
- Optional BERT integration – shows you understand modern transformer-based NLP.
- Production-grade architecture – Flask application factory, SQLAlchemy ORM, service layer, REST API, unit tests.
- Interactive Chart.js dashboard – visual analytics impress every viva examiner.
- Pluggable database – demonstrates understanding of environment-based configuration.
- Easy to extend – add email notifications, admin login, or deploy to Render or Railway in a day.
Watch Free Video Tutorials on YouTube
Subscribe to DecodeIT2 for daily Python project tutorials, AI walkthroughs, and final year project guides – all free.
Subscribe to DecodeIT2 on YouTube
Frequently Asked Questions (FAQ)
What is an AI Powered Resume Screening System?
It is an HR automation tool that automatically reads multiple resumes, extracts candidate details using NLP, and ranks each candidate against a job description using a weighted match score. It replaces hours of manual screening with a few seconds of automated analysis.
Which technologies are used in this Resume Screening project?
The project uses Python 3, Flask, SQLAlchemy, spaCy for NLP, scikit-learn for TF-IDF and cosine similarity, PyMuPDF and python-docx for document parsing, Chart.js for the dashboard, and openpyxl for Excel export.
Does this project use real machine learning or just keyword matching?
Both. The match engine combines exact skill overlap with TF-IDF cosine similarity, and optionally a BERT semantic model via sentence-transformers, so it captures contextual similarity instead of relying on keyword matches alone.
Is this project suitable for MCA, BCA, B.Tech, and MBA final year submission?
Yes. It is an advanced-level project that covers AI, NLP, machine learning, web development, and HR-Tech – making it equally strong for technical (MCA, BCA, B.Tech) and management (MBA HR / IT) submissions.
Can this system handle PDF and Word resumes?
Yes. PyMuPDF handles PDF resumes and python-docx handles DOCX files. The parser is built to deal with multi-column layouts and messy formatting commonly found in real resumes.
Can I switch the database from SQLite to MySQL?
Yes. Change the
DATABASE_URLvariable in the.envfile to a MySQL connection string and restart the app – tables are created automatically by SQLAlchemy.Does this project include a report, PPT, and synopsis?
Yes. The download package includes the complete source code along with the project report, synopsis, and PPT ready for academic submission.

[…] AI-Powered Resume Screening System in Python […]
[…] AI-Powered Resume Screening System in Python […]
[…] project is useful for exploring NLP and document processing. You can also read the AI-Powered Resume Screening System guide on UPDATEGADH for project details and implementation […]