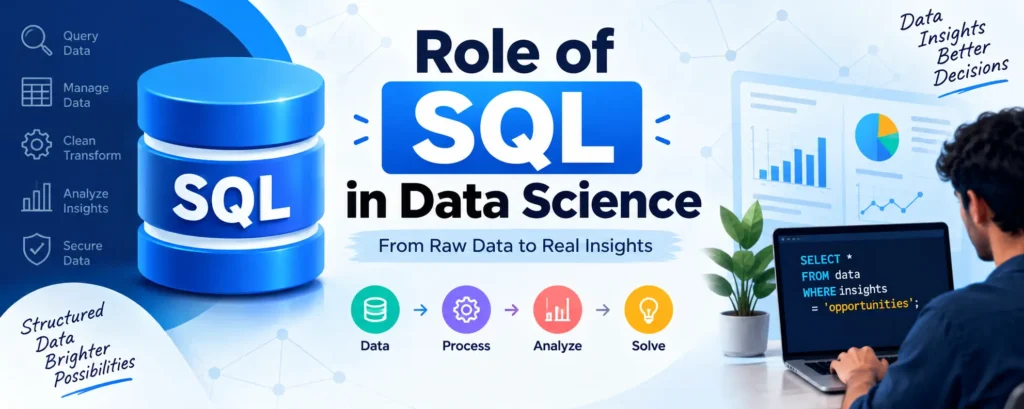
Role of SQL in Data Science
SQL (Structured Query Language) is one of the most important skills for anyone working in data science. It allows data scientists to retrieve, manage, clean, transform, and analyze data stored in relational databases.
Almost every data science project starts with data, and much of that data is stored in databases. Because of this, knowing how to work with SQL can make it much easier to access the information needed for analysis, visualization, and machine learning.
In this guide, we will explore the role of SQL in data science and understand how SQL supports different stages of the data science workflow.
Table of Contents
Complete Advance AI Topics: Click Here
SQL Tutorial: Click Here
Introduction to SQL
SQL is a domain-specific language used to communicate with relational databases. It provides a standardized way to store, retrieve, update, and manage structured data.
From small applications to large enterprise systems, relational databases are widely used for storing important business information. SQL provides the foundation for working with these databases efficiently.
Data Collection and Storage
Data collection and storage are essential parts of every data science project. Organizations collect information from many sources, including web applications, sensors, social media platforms, business applications, and internal systems.
SQL helps organizations create and manage databases where this information can be stored in an organized manner. Data scientists can work with tables, relationships, and database structures to access the information required for their projects.
Popular database management systems such as MySQL, PostgreSQL, SQL Server, and Oracle use SQL as their primary language for working with structured data.
Data Retrieval and Querying
After data has been collected and stored, data scientists need to retrieve the relevant information for analysis. SQL provides powerful querying capabilities that make this process efficient.
Using SQL, data scientists can filter records, combine tables, select specific columns, and retrieve only the data required for a particular analysis.
For example, an e-commerce database might contain separate tables for customers, orders, products, and order details. SQL can combine these tables to retrieve useful information.
SELECT customer_name, order_date, product_name, price
FROM customers
JOIN orders
    ON customers.customer_id = orders.customer_id
JOIN order_details
    ON orders.order_id = order_details.order_id
JOIN products
    ON order_details.product_id = products.product_id
WHERE order_date >= '2023-01-01';
This query retrieves customer names, order dates, product names, and prices for orders placed on or after January 1, 2023.
Data Cleaning and Transformation
Real-world datasets are rarely perfect. They can contain duplicate records, missing values, inconsistent formats, and incorrect data types.
SQL provides several operations that can help data scientists prepare data before analysis or modeling.
- Removing or handling null values
- Identifying and fixing duplicate records
- Changing data types
- Updating incorrect values
- Transforming data into a useful format
Commands such as UPDATE, DELETE, and INSERT can be used when modifying and preparing database records.
Data Aggregation and Summarization
Data aggregation is important when a data scientist needs to summarize large datasets and identify useful patterns.
SQL provides functions such as SUM(), AVG(), COUNT() along with GROUP BY to perform calculations and create summaries.
For example, SQL can be used to calculate total sales revenue for each region or determine the average customer age for different cities.
Exploratory Data Analysis (EDA)
Exploratory Data Analysis, commonly known as EDA, helps data scientists understand datasets before building models or making important decisions.
During EDA, professionals look for patterns, unusual values, relationships, and possible anomalies in the data.
SQL makes this process easier by allowing data scientists to quickly filter, group, sort, and summarize large amounts of structured data.
Feature Engineering
Feature engineering is an important step in machine learning. Good features can help machine learning models identify useful patterns in data.
SQL can support feature engineering by allowing data scientists to:
- Combine information from multiple datasets
- Create calculated fields
- Generate aggregated statistics
- Calculate customer-related metrics
- Prepare structured features for machine learning
For example, SQL can help calculate metrics such as customer lifetime value or purchase frequency. These engineered features can then be passed to the modeling stage.
Model Training Data Preparation
Before a machine learning model can be trained, the data needs to be prepared properly. This may involve selecting records, creating balanced datasets, sampling data, and preparing training and testing datasets.
SQL can perform many of these preprocessing tasks efficiently, helping data scientists create datasets that are suitable for machine learning workflows.
Integration with Programming Languages
SQL does not have to be used separately from programming languages. It works alongside popular languages such as Python, R, and Java.
For example, Python applications can use tools such as SQLAlchemy, while R workflows can use tools such as dplyr to work with database data.
This combination creates an efficient workflow where SQL handles data retrieval and manipulation, while Python or R can be used for statistical analysis, visualization, and machine learning.
Database Optimization
Data science projects can involve very large datasets, making database performance an important consideration.
SQL and relational database systems provide techniques that can improve query and database performance.
- Creating appropriate indexes
- Writing efficient SQL queries
- Analyzing SQL execution plans
- Identifying database bottlenecks
Understanding these techniques helps data scientists work more effectively with large volumes of data.
Data Visualization
Visualization helps data professionals understand patterns and communicate insights. SQL often plays an important role before the visualization stage by preparing the required dataset.
Data retrieved and aggregated using SQL can then be visualized with tools such as Tableau, Power BI, Matplotlib, and Seaborn.
By preparing clean and structured datasets, SQL provides a strong foundation for meaningful visualizations and analysis.
Scalability and Big Data
SQL has also evolved to support modern big data environments. Technologies such as Apache Hive and Apache Spark SQL allow professionals to use SQL-like queries when working with very large datasets.
This means data scientists who already understand SQL can apply their knowledge to distributed data processing environments without having to learn an entirely different way of querying data.
Security and Data Privacy
Data security and privacy are important considerations when working with business and customer data. SQL-based database systems provide mechanisms that can support secure data management.
- Role-based access controls
- Data encryption
- Auditing and logging
- Controlled access to sensitive information
Data scientists need to handle data responsibly, particularly when working with information subject to privacy and compliance requirements.
Collaboration and Documentation
Data science projects often involve multiple team members. Well-organized and documented SQL scripts make it easier for teams to understand how data is being processed.
Good SQL documentation can support:
- Reproducibility of analysis
- Easier onboarding for new team members
- Greater transparency in data workflows
- Better collaboration between team members
SQL scripts can also be maintained using version control systems such as Git.
Monitoring and Maintenance
SQL can also be used for database monitoring and maintenance tasks. Scheduled queries can help monitor data quality, check ETL pipeline health, and identify unusual changes in datasets.
These processes can help organizations maintain reliable data over time and identify problems before they affect downstream analysis.
Model Deployment and Integration
Databases remain important even after a machine learning model has been developed. Production applications often need to retrieve current data and store prediction results.
SQL can support machine learning deployment by helping with tasks such as:
- Creating stored procedures
- Retrieving live data for predictions
- Storing model outputs
- Maintaining prediction-related records
This integration allows machine learning systems to work with real business data and support practical applications.
Version Control and Collaboration
SQL scripts and database-related code can be maintained under version control. Using Git allows teams to track changes and collaborate more effectively.
Version control can help teams:
- Track changes to SQL queries
- Collaborate on database schemas
- Maintain a history of modifications
- Review changes made by team members
Data Governance
Data governance is an important part of managing data within an organization. SQL and database systems can support several governance-related activities.
- Enforcing data retention policies
- Tracking data lineage
- Managing access to sensitive information
- Maintaining data consistency
These capabilities can contribute to a stronger and more organized data governance framework.
Real-Time Data Analysis
Modern data systems increasingly require real-time analysis. Technologies such as Apache Kafka and Apache Flink allow SQL-based approaches to be used with streaming data.
Data professionals can use these technologies to analyze information as it arrives, monitor changing conditions, and support faster decision-making.
Challenges and Limitations of SQL in Data Science
Although SQL is extremely useful for data science, it also has some limitations.
- Structured Data Focus: SQL is primarily designed for structured data and is not the ideal tool for directly handling unstructured data such as images and videos.
- Complex Queries: Large and complicated SQL queries can become difficult to maintain, understand, and optimize.
- Horizontal Scalability: Scaling traditional relational databases horizontally can be more complex than using some NoSQL alternatives.
- Performance: Poorly written queries can result in slow database operations, especially when working with large datasets.
For these reasons, SQL is usually combined with other technologies rather than being used as the only tool in a modern data science workflow.
Advantages of SQL in Data Science
- Data Manipulation and Retrieval: SQL is highly effective for working with structured datasets.
- Data Cleaning: SQL provides useful operations for preparing and transforming data.
- Data Integration: Multiple tables and data sources can be combined using SQL.
- Query Optimization: Indexing and efficient queries can improve database performance.
- Scalability: Modern database systems can handle large quantities of structured data.
- Security: Database systems provide access control, encryption, and auditing capabilities.
- Historical Data Analysis: SQL is useful for analyzing trends and historical records.
- Advanced Analytics: SQL can work alongside Python and R for statistical and machine learning workflows.
- Data Consistency: Relational databases provide mechanisms for maintaining data integrity and consistency.
YT:- DecodeIT
Disadvantages of SQL in Data Science
- Structured Data Focus: SQL is not designed primarily for unstructured data such as images and videos.
- Learning Curve: Beginners may need time to understand SQL syntax, joins, aggregation, and query optimization.
- Performance Issues: Inefficient queries can become slow when working with large datasets.
- Horizontal Scalability: Scaling relational databases can be more complex and expensive compared with some NoSQL systems.
Conclusion
SQL continues to play an important role in data science. From collecting and retrieving data to cleaning, exploration, feature engineering, visualization, and machine learning preparation, SQL can be useful throughout the data science workflow.
For aspiring data scientists, learning SQL is an important step toward becoming comfortable with real-world data. Whether you are preparing datasets for machine learning, creating dashboards, exploring business data, or working with databases, strong SQL skills can make your workflow more efficient.
If you are starting your journey in data science, make SQL one of your core skills. The journey may begin with simple queries, but those queries can lead to valuable insights, better decisions, and stronger data science capabilities.
Keywords
role of sql in data science, SQL in data science, importance of SQL in data science, SQL for data science, SQL for data analysis, what is SQL, SQL data science jobs, SQL and data science, SQL for machine learning, data science SQL