How to Extract PDF Tables with Python
PDF files are widely used for reports, research papers, invoices, financial statements, academic documents, business reports, and other types of structured information. However, extracting useful data from PDF tables manually can be time-consuming, especially when a document contains dozens or hundreds of pages.
Python provides several powerful libraries that can automate PDF table extraction. When Python-based extraction is combined with AI, the process can become even more useful because AI can help identify table content, understand column meanings, clean extracted values, and convert unstructured results into a more usable format.
In this tutorial, we will learn How to Extract PDF Tables with AI and Python. We will use Python, PyMuPDF, and pandas to detect and process tables from a PDF document. We will also understand how AI can be used after extraction to clean and organize the extracted information.
Table of Contents
Complete Advance AI Topics: Click Here
Real Time Projects on YouTube:- DecodeIT
Why Extract Tables from PDF Files?
PDF documents are designed primarily for displaying information rather than manipulating data. A table that looks perfectly organized to a human reader may internally contain individual text elements positioned on a page.
Manually copying such information into Excel or a database can introduce errors and consume a lot of time. Automated extraction allows developers and students to convert PDF tables into structured data that can be analyzed with Python.
Once the table has been extracted, the data can be saved as CSV or Excel files, inserted into databases, visualized using charts, or processed using machine learning and AI systems.
Technologies Used
| Technology | Purpose |
|---|---|
| Python | Programming language used for automation |
| PyMuPDF | Detecting and extracting tables from PDF pages |
| Pandas | Working with extracted tabular data |
| AI | Cleaning, interpreting, and organizing extracted information |
| Source document containing the table |
How PDF Table Extraction Works
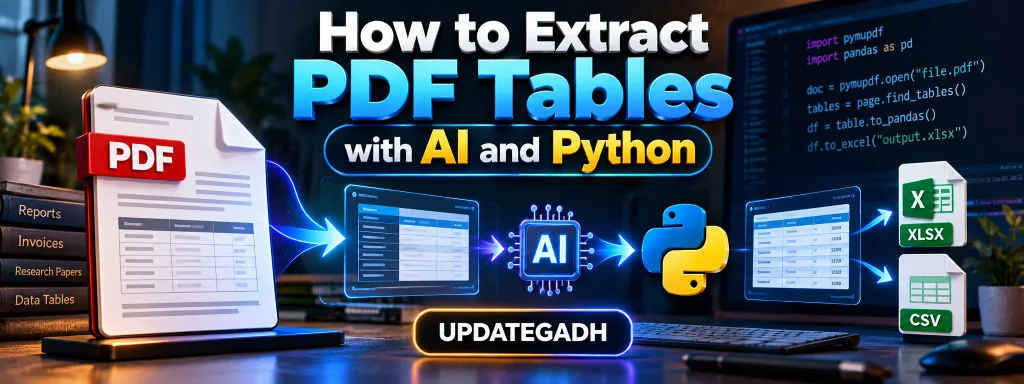
The basic workflow is straightforward. First, Python opens the PDF document. Each page is inspected for tables. The detected table is then converted into rows and columns. Finally, pandas can be used to process the extracted information.
PyMuPDF provides a find_tables() method that can locate tables on a PDF page and provides methods for extracting their contents or converting them into pandas DataFrames. Its documentation also notes that table detection can use either graphical table structures or text-based strategies depending on the document.
Step 1: Create the Python Project
Create a new folder for the project and open it in Visual Studio Code. It is recommended to create a virtual environment before installing the required packages.
python -m venv venvActivate the virtual environment on Windows:
venv\Scripts\activateNow install the required libraries:
pip install pymupdf pandas openpyxlStep 2: Add the PDF File
Create a folder named input inside your project and place your PDF file inside it. For example:
PDF-Table-Extractor/
│
├── input/
│   └── sample.pdf
│
├── output/
│
└── extract_tables.py
The PDF should preferably contain selectable text or a structured table. Scanned or image-only PDFs may require OCR or an AI/vision-based workflow before reliable table extraction can be performed.
Step 3: Extract Tables Using PyMuPDF
Create a file named extract_tables.py. The following Python program opens the PDF, checks every page, detects tables, converts them into pandas DataFrames, and saves the results as Excel files.
import pymupdf
import pandas as pd
import os

pdf_path = "input/sample.pdf"
output_folder = "output"

os.makedirs(output_folder, exist_ok=True)

doc = pymupdf.open(pdf_path)

table_number = 1

for page_number, page in enumerate(doc, start=1):

    tables = page.find_tables()

    print(f"Page {page_number}: {len(tables.tables)} table(s) found")

    for table in tables.tables:

        df = table.to_pandas()

        print(df)

        output_file = os.path.join(
            output_folder,
            f"table_{table_number}.xlsx"
        )

        df.to_excel(output_file, index=False)

        table_number += 1

doc.close()

print("Table extraction completed.")
PyMuPDF’s documentation provides the same general extraction workflow: open a document, access a page, call find_tables(), and extract the detected table.
Step 4: Save the Extracted Table as CSV
Excel is useful for users who want to inspect the data manually, while CSV is convenient for data analysis and machine learning workflows.
You can replace the Excel export code with:
output_file = os.path.join(
    output_folder,
    f"table_{table_number}.csv"
)

df.to_csv(output_file, index=False)
This creates a separate CSV file for every detected table.
Step 5: Clean the Extracted Data
PDF extraction does not always produce perfectly clean data. Empty rows, unnecessary spaces, incorrect headers, and inconsistent values may appear in the resulting DataFrame.
Pandas can be used to perform basic cleaning:
df = df.dropna(how="all")

df.columns = [
    str(column).strip()
    for column in df.columns
]

df = df.map(
    lambda value: value.strip()
    if isinstance(value, str)
    else value
)

print(df)
This removes completely empty rows and unnecessary spaces from text values.
How AI Helps with PDF Table Extraction
Traditional Python libraries are very useful for detecting table structures, but AI can be helpful when the extracted content requires interpretation or cleanup.
For example, suppose a PDF contains columns such as Employee Name, Salary, and Joining Date, but extraction produces inconsistent spacing and formatting. An AI model can be instructed to identify the intended column structure, normalize values, identify unusual entries, and return structured information.
A practical AI workflow can look like this:
PDF
 ↓
Python
 ↓
Table Detection
 ↓
Pandas DataFrame
 ↓
Data Cleaning
 ↓
AI Processing
 ↓
Structured Dataset
 ↓
CSV / Excel / Database
AI should be treated as an additional processing layer rather than assuming it will always extract every table correctly. The original PDF and extracted values should be checked when the information is important.
Example AI Prompt for Extracted Tables
After extracting a table, you can provide its text or structured representation to an AI system with a prompt such as:
Analyze the following extracted PDF table.

1. Identify the column names.
2. Remove unnecessary spaces.
3. Preserve the original values.
4. Standardize dates where possible.
5. Identify empty or suspicious values.
6. Return the cleaned information as a structured table.

Do not invent missing information.
This approach is especially useful when the PDF contains inconsistent formatting or when the extracted table needs to be prepared for further analysis.
Using Camelot as Another Python Option
Camelot is another Python library specifically designed for extracting tabular data from PDFs. Its current documentation describes multiple parsing approaches, including lattice and stream-style extraction, and it can export extracted tables to formats such as CSV and Excel.
For a PDF containing clearly drawn table lines, a basic Camelot example is:
import camelot

tables = camelot.read_pdf(
    "input/sample.pdf",
    pages="all"
)

print(tables)

tables.export(
    "output/tables.csv",
    f="csv"
)
Camelot’s documentation also explains that its traditional extraction methods are intended for text-based PDFs, while its newer optional machine-learning and OCR components can be used for more difficult borderless or scanned documents.
PyMuPDF vs Camelot
| Feature | PyMuPDF | Camelot |
|---|---|---|
| PDF table detection | Yes | Yes |
| Pandas integration | Yes | Yes |
| CSV/Excel workflows | Yes | Yes |
| Text-based PDFs | Yes | Yes |
| Scanned PDFs | Requires additional OCR workflow | Optional OCR support |
| AI/ML assistance | External processing can be added | Optional ML functionality is available |
The appropriate library depends on the structure of the PDF. PyMuPDF provides a direct table-detection API through find_tables(), while Camelot provides specialized table parsers and export options.
Handling Difficult PDF Tables
Not every PDF table is created in the same way. A table with clearly defined borders is generally easier to detect than one created using only text positioning.
PyMuPDF’s documentation explains that table detection can fail when a document has no visible borders or when the table is represented using unusual layouts. In such situations, text-based detection strategies or additional processing may be required.
For scanned documents, OCR becomes important because the PDF may contain an image instead of an actual text layer. In these cases, the workflow can be extended with OCR and AI-based document understanding before creating the final DataFrame.
Applications of PDF Table Extraction
Automated PDF table extraction can be useful in many practical situations. Students can use it for research projects and data analysis. Businesses can process reports, invoices, financial statements, and operational documents. Developers can create systems that automatically convert PDF information into databases or analytics dashboards.
The extracted data can also become an input for machine learning models, statistical analysis, reporting systems, and AI-powered document-processing applications.
Installation Guide for VS Code
Follow these steps to run the project in Visual Studio Code:
- Install Python on your computer.
- Install Visual Studio Code.
- Create a project folder.
- Open the folder in VS Code.
- Open the integrated terminal.
- Create a virtual environment.
- Activate the virtual environment.
- Install PyMuPDF, pandas, and openpyxl.
- Create the
inputandoutputfolders. - Place your PDF inside the
inputfolder. - Create
extract_tables.py. - Run the Python program.
python extract_tables.pyAfter execution, the extracted tables will be stored inside the output folder.
Usage
This project can be used by students, researchers, developers, data analysts, and businesses that regularly work with structured information stored in PDF documents. A developer can extend the project by adding a web interface, database storage, OCR support, AI-based validation, or automatic report generation.
Contributing
Contributions can improve this project by adding better table-detection techniques, OCR support, improved data cleaning, AI-based table validation, database integration, and additional export formats. Developers can also improve error handling and support for more complex PDF layouts.
Final Thoughts
Learning How to Extract PDF Tables with AI and Python is a useful skill for students and developers working with documents and data. Python makes it possible to automate the extraction process, while libraries such as PyMuPDF and Camelot provide practical tools for detecting and processing tables.
Adding AI as a processing layer can make the workflow more flexible by helping clean, interpret, and organize extracted information. However, important data should always be validated against the original PDF, especially when the document contains financial, academic, legal, or business-critical information.
Complete Advance AI Topics: Click Here
Python Tutorial: Click Here
Keywords: How to Extract PDF Tables with AI and Python, PDF table extraction Python, extract tables from PDF Python, AI PDF table extraction, PyMuPDF table extraction, Camelot PDF extraction, Python PDF data extraction, extract PDF to Excel, PDF table to CSV, AI document processing,How to Extract PDF Tables with AI and Python, PDF Table Extraction Python, Extract PDF Tables with Python, AI PDF Table Extraction, Python PDF Extraction, PyMuPDF, Camelot Python, PDF to Excel Python, PDF to CSV Python, AI Document Processing, PDF Data Extraction, Python AI Tutorial, PDF Automation, Table Extraction Python, Python Data Extraction, AI Data Processing, PDF Parsing, Python PDF Tutorial, Document Automation, Artificial Intelligence