Active Learning Machine Learning
In machine learning, data is king. However, having a large amount of data is not always enough. For supervised learning, we also need high-quality labeled data, and creating those labels can be expensive and time-consuming.
Labeling data often requires human effort, domain expertise, and considerable resources. This is where Active Learning becomes useful. Instead of labeling the entire dataset in advance, active learning allows a machine learning model to select the data points that are most valuable to label.
By focusing labeling efforts on the most informative examples, active learning can help build effective models while using fewer labeled samples.
Table of Contents
Complete Advance AI Topics: Click Here
SQL Tutorial: Click Here
What Is Active Learning?
Active Learning is a machine learning technique in which an algorithm interactively selects data points and asks a human or another labeling system, known as an oracle, to provide their labels.
The main goal is simple: train better machine learning models with less labeled data.
Instead of labeling a large random sample, active learning concentrates on examples that the model is uncertain about or that are expected to provide the greatest improvement in model performance.
This approach can be particularly valuable in fields such as healthcare, legal technology, and scientific research, where obtaining expert-labeled data can be expensive or difficult.
Key Strategies in Active Learning
Active learning uses different strategies to determine which unlabeled data points should be selected for labeling. Some of the most common approaches are discussed below.
1. Uncertainty Sampling
Uncertainty Sampling is one of the most widely used active learning strategies. The model selects the data points about which it is least confident.
- Least Confidence Sampling: Select samples where the predicted probability of the most likely class is the lowest.
- Margin Sampling: Select points where the difference between the probabilities of the top two classes is the smallest.
- Entropy Sampling: Select samples with the highest prediction entropy. Higher entropy indicates greater uncertainty.
2. Query-by-Committee (QBC)
Query-by-Committee (QBC) uses multiple models, known as a committee, that are trained using the current labeled dataset.
The system selects data points where the models disagree the most.
- Different model architectures or initializations can be used to create model diversity.
- Disagreement can be measured using techniques such as vote entropy or KL divergence.
3. Expected Model Change
Expected Model Change focuses on identifying samples that are expected to produce the largest change in the machine learning model after being labeled.
- Gradient-based methods can be used to estimate how much the model could change when a sample is added.
- This approach is useful when the goal is to maximize the learning impact of every new labeled example.
4. Density-Based Methods
Density-Based Methods focus on selecting data points that are representative of the overall dataset rather than simply choosing unusual or isolated samples.
- Clustering: Select representative points from different clusters.
- Uncertainty + Density: Prioritize uncertain samples that are located in dense and representative regions of the data.
5. Diversity Sampling
Diversity Sampling aims to select a wide range of different examples while avoiding redundant samples.
- Submodular Optimization: Use diversity-focused mathematical techniques to select varied data points.
- Maximal Marginal Relevance (MMR): Balance the informativeness of a sample with its diversity compared with already selected samples.
The Active Learning Workflow
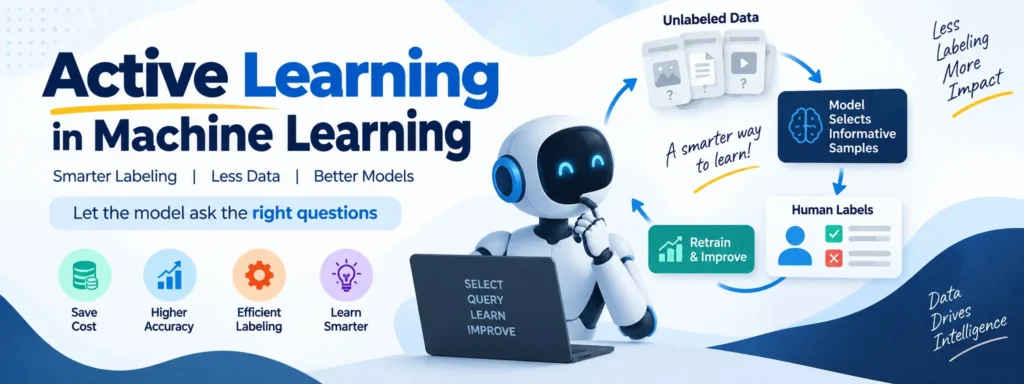
Active learning generally follows an iterative process. The model repeatedly selects useful samples, obtains their labels, and updates itself with the newly labeled data.
1. Initial Model Training
- Start with a small labeled dataset containing either random or representative samples.
- Train an initial machine learning model using an appropriate algorithm such as logistic regression, decision trees, or neural networks.
2. Query Selection
- Apply an active learning query strategy to identify the most informative unlabeled data points.
- Select an appropriate batch size based on available resources and project requirements.
3. Label Acquisition
- Send the selected samples for labeling by human experts, crowdsourcing systems, or automated labeling processes.
- Maintain high-quality labels because incorrect labels can negatively affect model performance.
4. Model Update
- Add the newly labeled samples to the existing training dataset.
- Retrain or update the model using the expanded labeled dataset.
5. Iteration
Repeat the process of selecting, labeling, and retraining. The model should be evaluated continuously using a validation dataset to measure its progress.
6. Stopping Criteria
The active learning process can be stopped when one of the following conditions is reached:
- The target model accuracy has been achieved.
- The available labeling budget has been exhausted.
- Additional labeled samples provide only small or diminishing improvements.
Benefits of Active Learning
Active learning can make the data labeling process more efficient by concentrating human effort on the samples that are most useful to the model.
1. Cost Efficiency
- Fewer Labels, Greater Impact: Reduce labeling requirements by selecting only valuable samples.
- Focused Human Effort: Experts can spend more time on difficult and informative examples instead of labeling large amounts of routine data.
2. Better Model Performance
- Faster Convergence: Informative examples can help the model learn more efficiently.
- Higher Accuracy: Active learning can be especially useful for difficult, uncertain, or ambiguous examples.
3. Handling Class Imbalance
- Actively select samples from underrepresented classes.
- Improve model performance across different categories rather than allowing the dominant class to control the training process.
4. Scalability
- Active learning can be useful with large datasets because the complete dataset does not need to be labeled.
- It can also be incorporated into scalable machine learning and data-labeling pipelines.
5. Effective with Limited Data
- Make better use of small labeled datasets.
- This can be valuable in areas such as medicine and scientific research, where labeled data may be limited or expensive to obtain.
6. Robustness and Generalization
- By focusing on borderline and ambiguous examples, active learning can help improve model robustness.
- The model can become better prepared to handle unseen real-world data.
Download New Real Time Projects: Click here
Final Thoughts
Active Learning changes the traditional approach to data labeling in machine learning. Instead of labeling every available data point, the model helps identify the examples that are most useful for improving its learning.
By allowing machine learning models to ask for the right data, organizations can reduce labeling costs, use expert time more effectively, and build models with fewer labeled examples.
In a world where data is abundant but high-quality labeled data can be difficult to obtain, active learning is an important technique for developing efficient and scalable machine learning systems.
Keywords: active learning machine learning, active learning machine learning example, active learning tutorial, active learning strategies, active learning in deep learning, active learning NLP, active learning query strategies, active learning vs reinforcement learning, active learning ML, active learning methods, active learning model, machine learning active learning