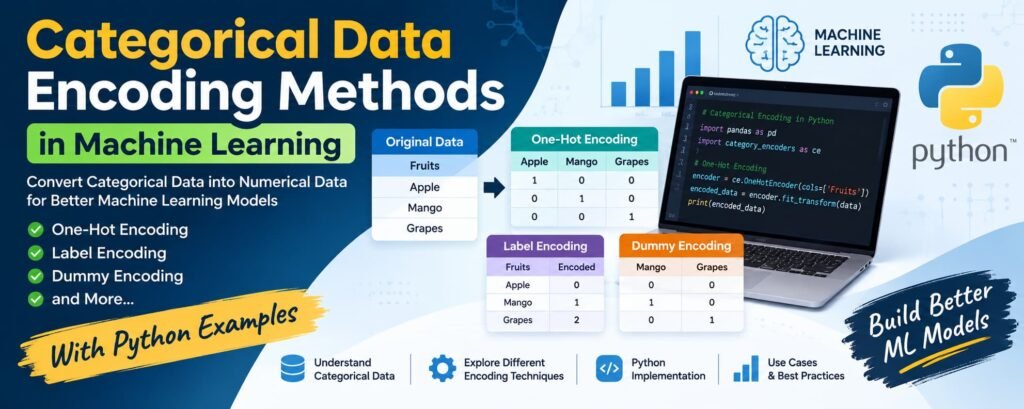
Categorical Data Encoding Methods
One of the most common challenges in data science and machine learning is handling categorical data. Qualitative characteristics such as color, locality, or brand are represented using categorical variables. Since most machine learning algorithms require numerical input, categorical data must be converted into a numerical format. This process of converting categorical values into numerical representations is called categorical data encoding.
In this tutorial, we will explore different categorical data encoding methods, their use cases, advantages, disadvantages, and their implementation in Python.
Table of Contents
Complete Advance AI Topics: Click Here
SQL Tutorial: Click Here
What is Categorical Data?
Categorical data represents qualitative characteristics or properties. These variables are generally textual and describe attributes that do not always have a direct numerical meaning.
Categorical data is mainly divided into two types:
- Nominal Data: Categories that do not have any specific order. Examples include car brands, fruit types, and cities.
- Ordinal Data: Categories that have a meaningful order or hierarchy. Examples include education levels such as high school, bachelor’s, and master’s, or ratings such as low, medium, and high.
Having a clear understanding of categorical data is essential when preparing data for machine learning models. Machine learning algorithms generally cannot work directly with text-based categories, so appropriate encoding is required to represent these values numerically.
Categorical Data Encoding Methods
Categorical encoding methods are techniques used to convert categorical values into numerical representations that machine learning algorithms can process.
1. One-Hot Encoding
Best for: Nominal data where categories do not have an inherent order.
How it works:
With one-hot encoding, each unique category is converted into its own column containing binary values such as 0 and 1.
Example:
Original Data:

Fruits
-------
Apple
Mango
Grapes
After one-hot encoding:
Apple | Mango | Grapes
1     | 0     | 0
0     | 1     | 0
0     | 0     | 1
Advantages:
- Prevents false ordinal relationships between categories.
- Widely supported by machine learning libraries.
Disadvantages:
- Can significantly increase dimensionality when the dataset contains many unique categories.
Python Implementation:
import category_encoders as ce
import pandas as pd

data = pd.DataFrame({
    'Fruits': [
        'Apple', 'Banana', 'Pineapple',
        'Grapes', 'Orange', 'Pomegranate',
        'Watermelon'
    ]
})

encoder = ce.OneHotEncoder(
    cols=['Fruits'],
    handle_unknown='return_nan',
    return_df=True,
    use_cat_names=True
)

encoded_data = encoder.fit_transform(data)

print(encoded_data)
2. Label Encoding (Ordinal Encoding)
Best for: Ordinal data where categories have a natural order.
How it works:
Each category is assigned a unique numerical value. For example, categories can be represented as Low = 0, Medium = 1, High = 2.
Example:
Original:

Class
------
First
Second
Third
After encoding:
Class
-----
0
1
2
Advantages:
- Requires less memory than methods that create many additional columns.
- Suitable for ordered categorical data.
Disadvantages:
- Can introduce an artificial ordinal relationship when used with nominal data.
Python Implementation:
import category_encoders as ce
import pandas as pd

data = pd.DataFrame({
    'Fruits': [
        'Apple', 'Banana', 'Orange', 'Pineapple',
        'Apple', 'Grapes', 'Watermelon', 'Banana',
        'Orange', 'Pineapple', 'Pomegranate',
        'Watermelon'
    ]
})

encoder = ce.OrdinalEncoder(
    cols=['Fruits'],
    return_df=True,
    mapping=[{
        'col': 'Fruits',
        'mapping': {
            'Apple': 1,
            'Banana': 2,
            'Orange': 3,
            'Grapes': 4,
            'Watermelon': 5,
            'Pineapple': 6,
            'Pomegranate': 7
        }
    }]
)

label_encoded_data = encoder.fit_transform(data)

print(label_encoded_data)
3. Dummy Encoding
Best for: Nominal data, particularly in regression-based applications.
How it works:
Dummy encoding is similar to one-hot encoding, but one category is dropped to avoid redundancy and potential multicollinearity. If a categorical variable contains n categories, dummy encoding generally creates n – 1 binary columns.
Example:
Region: North, South, East, West

Dummy encoding creates columns for:
South
East
West

If all three values are 0, the category is North.
Advantages:
- Reduces redundant information.
- Helps prevent multicollinearity in suitable regression settings.
Disadvantages:
- The reference category needs to be selected and interpreted carefully.
Python Implementation:
import pandas as pd

data = pd.DataFrame({
    'Fruits': [
        'Apple', 'Banana', 'Orange', 'Pineapple',
        'Apple', 'Grapes', 'Watermelon', 'Banana',
        'Orange', 'Pineapple', 'Pomegranate',
        'Watermelon'
    ]
})

dummy_encoded = pd.get_dummies(
    data,
    columns=['Fruits'],
    drop_first=True
)

print(dummy_encoded)
Other Categorical Encoding Techniques
Besides one-hot, label, and dummy encoding, several other techniques can be useful for advanced machine learning applications.
4. Frequency Encoding
Frequency encoding replaces each category with its frequency or occurrence count in the dataset.
Advantages: It can represent the relative importance of common and rare categories.
Disadvantages: The resulting values can be less intuitive to interpret.
5. Target Encoding (Mean Encoding)
Target encoding represents each category using the mean value of the target variable associated with that category.
Advantages: It can capture the relationship between categorical variables and the target.
Disadvantages: It can cause overfitting if not implemented carefully.
6. Hash Encoding
Hash encoding uses a hashing function to map categories into a fixed number of columns.
Advantages: It is useful for datasets containing high-cardinality categorical variables.
Disadvantages: Different categories can sometimes map to the same column, resulting in hash collisions.
7. Leave-One-Out Encoding (LOO)
Leave-One-Out encoding replaces a category with its mean target value while excluding the current row from the calculation.
Advantages: It can reduce some of the overfitting associated with standard target encoding.
Disadvantages: It is more complex to implement and requires careful handling.
8. Weight of Evidence (WOE) Encoding
Weight of Evidence encoding represents categories using the log-odds relationship between the target classes. It is commonly used in applications such as credit scoring and binary classification.
Advantages: It can work well for binary classification problems.
Disadvantages: The resulting values require careful interpretation.
9. Effect Encoding
Effect encoding is similar to dummy encoding, but instead of comparing each category against a selected reference category, it represents categories in relation to the overall mean.
Advantages: It can provide useful representations when comparing category effects against the overall population.
How to Choose the Right Encoding Method?
The best categorical encoding technique depends on the type of data and the machine learning problem.
| Encoding Method | Best Used For | Main Consideration |
|---|---|---|
| One-Hot Encoding | Nominal data | Can increase dimensionality |
| Ordinal Encoding | Ordinal data | Preserves category order |
| Dummy Encoding | Nominal data and regression | Uses a reference category |
| Frequency Encoding | High-cardinality categories | May reduce interpretability |
| Target Encoding | Categories related to a target | Risk of overfitting |
| Hash Encoding | High-cardinality data | Possible hash collisions |
| WOE Encoding | Binary classification | Requires careful interpretation |
Download New Real-Time Projects: Click here
Conclusion
Correctly encoding categorical data is an important step in building effective machine learning models. The appropriate encoding technique depends on several factors, including the type of categorical variable, machine learning algorithm, dataset size, and number of unique categories.
One-hot encoding is commonly used for nominal variables, while ordinal encoding is more appropriate when categories have a meaningful order. For datasets with high-cardinality variables, techniques such as frequency, target, or hash encoding may be more suitable.
By understanding the different categorical data encoding methods and selecting the right approach, you can build a more effective preprocessing workflow for your machine learning projects.
Keywords
categorical encoding in machine learning, encoding categorical variables python, one hot encoding, how to encode categorical data in python pandas, encoding techniques in machine learning, one-hot encoding in machine learning, mapping variables to encoding in data science, label encoding, encoding categorical data in machine learning, categorical encoding, categorical data encoding methods, what is encoding categorical data, ways to encode categorical data, categorical encoding techniques, can categorical data be numeric