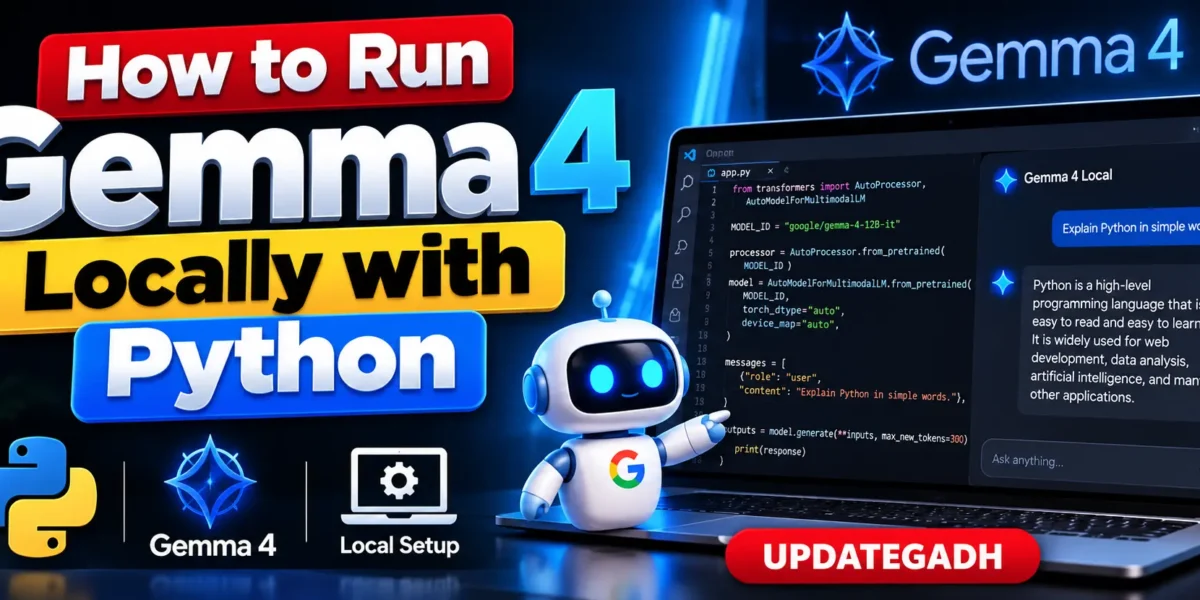
How to Run Gemma 4 Locally with Python
Running AI models locally is becoming an important skill for Python developers, students, and machine learning enthusiasts. Instead of sending every prompt to a cloud-based API, developers can run an open model directly on their own computer and build applications around it.
Gemma 4 is Google’s latest open model family, designed for reasoning, coding, agentic workflows, and multimodal applications. The family includes smaller E2B and E4B models for edge devices, along with larger 12B, 26B A4B, and 31B models for laptops, GPUs, workstations, and servers. Gemma 4 supports text and image input, while E2B, E4B, and 12B also support audio. The models support context windows of up to 256K tokens depending on the variant.
In this tutorial, we will learn How to Run Gemma 4 Locally with Python using the Hugging Face Transformers ecosystem. This approach allows you to load the model into Python and generate responses without depending on a remote inference API.
Table of Contents
Complete Advance AI Topics: Click Here
Real Time Projects on YouTube:- DecodeIT
What is Gemma 4?
Gemma 4 is a family of open-weight AI models developed by Google DeepMind. Google introduced Gemma 4 in April 2026 with multiple model sizes intended for different hardware and workloads. The family includes efficient edge models as well as larger models for more demanding reasoning and multimodal tasks.
The smaller E2B and E4B variants focus on memory and compute efficiency, while the 12B, 26B A4B, and 31B models target more capable local and workstation deployments. The 26B version uses a Mixture-of-Experts architecture and has approximately 3.8B active parameters during inference, despite having around 25.2B total parameters.
Gemma 4 Model Options
| Model | Architecture | Context | Suitable For |
|---|---|---|---|
| Gemma 4 E2B | Efficient | 128K | Edge devices and lightweight applications |
| Gemma 4 E4B | Efficient | 128K | Local AI and multimodal edge workloads |
| Gemma 4 12B | Unified | 256K | Laptops and multimodal applications |
| Gemma 4 26B A4B | Mixture of Experts | 256K | Powerful local GPU systems |
| Gemma 4 31B | Dense | 256K | High-performance workstations and servers |
For a first Python-based local experiment, the Gemma 4 12B model is a practical option on suitable hardware. Google specifically describes the 12B model as a laptop-oriented multimodal model and notes that it can run locally on dedicated GPU laptops with 16GB VRAM or unified memory.
Requirements
Before starting, make sure Python is installed and that your computer has enough memory for the Gemma 4 variant you want to use. Larger models require substantially more memory, especially when using higher-precision weights.
You should have:
- Python 3.10 or newer
- A suitable GPU or enough system memory for the selected model
- Hugging Face account access for Gemma model files where required
- PyTorch
- Transformers
- Accelerate
Hardware requirements depend heavily on model size, quantization, context length, and whether inference is performed on GPU or CPU. Do not assume that a model’s parameter count directly equals its required RAM or VRAM.
Step 1: Create a Python Project
Create a new folder for the project and open it in VS Code.
mkdir gemma4-python
cd gemma4-python
Create a virtual environment:
python -m venv venvActivate it on Windows:
venv\Scripts\activateOn macOS or Linux, use:
source venv/bin/activateStep 2: Install Required Python Libraries
Install the latest compatible versions of the main Python libraries:
pip install -U torch transformers accelerateThe official Gemma 4 12B model documentation recommends Transformers, PyTorch, and Accelerate for loading the model directly in Python.
Step 3: Get Access to the Gemma Model
Gemma model weights are distributed through platforms such as Hugging Face and Kaggle. Google provides the official Gemma 4 checkpoints, including the instruction-tuned models used for conversational generation.
For the example in this tutorial, we will use:
google/gemma-4-12B-itIf Hugging Face asks you to authenticate or accept the applicable model terms, complete that process before attempting to download the model.
Step 4: Create the Python File
Create a file named app.py. The following example loads Gemma 4 12B and generates a response from a text prompt.
from transformers import AutoProcessor, AutoModelForMultimodalLM

MODEL_ID = "google/gemma-4-12B-it"

processor = AutoProcessor.from_pretrained(MODEL_ID)

model = AutoModelForMultimodalLM.from_pretrained(
    MODEL_ID,
    dtype="auto",
    device_map="auto"
)

messages = [
    {
        "role": "system",
        "content": "You are a helpful Python programming assistant."
    },
    {
        "role": "user",
        "content": "Explain Python lists in simple words."
    }
]

inputs = processor.apply_chat_template(
    messages,
    tokenize=True,
    return_dict=True,
    return_tensors="pt"
).to(model.device)

outputs = model.generate(
    **inputs,
    max_new_tokens=300
)

response = processor.decode(
    outputs[0],
    skip_special_tokens=True
)

print(response)
The official Gemma 4 12B model card uses AutoProcessor and AutoModelForMultimodalLM for loading the model with Transformers.
Step 5: Run the Application
Save the file and execute it from your terminal:
python app.pyThe first execution can take time because Python needs to download the model files and initialize them. Once the model has been loaded, the application generates an answer locally.
How the Python Code Works
The AutoProcessor prepares the input for Gemma 4. It is especially useful because Gemma 4 supports multimodal inputs, depending on the selected model.
The AutoModelForMultimodalLM loads the Gemma 4 model itself. Using device_map=”auto” allows Transformers and Accelerate to determine an appropriate device placement based on the available hardware.
The apply_chat_template() method converts the conversation messages into the format expected by the model. Finally, generate() produces the model’s output.
Running Gemma 4 with a Smaller Model
If your hardware cannot comfortably handle the 12B model, Gemma 4 also provides smaller E2B and E4B variants designed for efficient local and edge inference. Google describes these models as being optimized for compute and memory efficiency, including deployment on devices such as phones, Raspberry Pi systems, and NVIDIA Jetson hardware.
For example, the Hugging Face GGUF ecosystem currently provides Gemma 4 E2B and E4B variants that can be used with local inference tools. The published E2B GGUF model lists approximately 5B total parameters and an approximately 4.97 GB Q8_0 file, while the E4B model lists approximately 8B total parameters and an approximately 8.03 GB Q8_0 file.
Alternative: Run Gemma 4 with Ollama
If your primary goal is simply to run Gemma 4 locally rather than directly controlling the model through Transformers, Ollama provides another convenient approach. Gemma 4 GGUF model pages provide Ollama commands for several model variants.
After installing Ollama, a supported Gemma 4 GGUF model can be started using a command such as:
ollama run hf.co/ggml-org/gemma-4-E4B-GGUF:BF16You can then connect a Python application to the local model server instead of downloading and managing model weights directly inside your Python process.
Using Gemma 4 for Python Projects
Once Gemma 4 is running locally, you can integrate it into many student and professional projects. Some useful applications include:
- Local Python coding assistants
- Document summarization tools
- Question-answering applications
- Local chatbots
- Programming education assistants
- Image and document understanding applications
- Offline AI utilities
- Agentic Python applications
Gemma 4 is particularly interesting for local development because its capabilities extend beyond traditional text generation. Google documents support for coding, reasoning, agentic workflows, and multimodal understanding across the model family.
Common Problems and Solutions
1. Out of Memory Error
If you receive a CUDA or memory-related error, the selected model may be too large for your available hardware. Try a smaller Gemma 4 variant, reduce the context size, or use a quantized model.
2. Model Access Error
If Hugging Face reports that the model cannot be accessed, check whether you have completed the required authentication or model access steps.
3. Slow Generation
CPU inference can be considerably slower than GPU inference for larger models. Using a supported GPU, smaller model, or optimized quantized format can improve local performance.
4. Transformers Compatibility
Gemma 4 requires a recent Transformers version with Gemma 4 architecture support. If your installation is outdated, upgrade it:
pip install -U transformers accelerateBenefits of Running Gemma 4 Locally
- Local processing: Your application can perform inference on your own hardware.
- Development flexibility: Python developers can directly integrate the model into applications.
- Offline workflows: After the model is downloaded, local inference can be used without sending each prompt to a remote inference endpoint.
- Multimodal capabilities: Supported Gemma 4 variants can work with text, images, and audio.
- Open model ecosystem: Gemma 4 is available through multiple local development frameworks and runtimes.
Conclusion
Running Gemma 4 locally with Python gives developers a practical way to experiment with modern open AI models directly from their own systems. With Hugging Face Transformers, PyTorch, and Accelerate, you can load an instruction-tuned Gemma 4 model and integrate it into Python applications.
The most important step is choosing a model that matches your hardware. Smaller E2B and E4B variants are designed for efficient deployments, while the 12B, 26B A4B, and 31B models provide progressively larger local workloads. Google also supports Gemma 4 through several local runtimes and developer tools, including Transformers, llama.cpp, MLX, Ollama, vLLM, LiteRT-LM, and others.
SEO Details
Keywords: How to Run Gemma 4 Locally with Python, Gemma 4 Python, Run Gemma 4 Locally, Gemma 4 Tutorial, Google Gemma 4, Gemma 4 Transformers, Local AI with Python, Gemma 4 12B, Python AI Tutorial,Gemma 4 PythonRun Gemma 4 LocallyGemma 4 TutorialGoogle Gemma 4Gemma 4 12BGemma 4 Local AIGemma 4 InstallationGemma 4 SetupGemma 4 with PythonLocal AI with PythonGemma 4 TransformersGemma 4 Hugging FaceGemma 4 PyTorchLocal LLM with PythonAI Models with PythonGenerative AI TutorialPython AI TutorialRun LLM LocallyOpen AI ModelsLocal AI Development,Gemma 4, Gemma 4 Tutorial, How to Run Gemma 4 Locally, Gemma 4 Python, Run Gemma 4 Locally, Google Gemma 4, Gemma 4 with Python, Gemma 4 12B, Gemma 4 Local AI, Local AI with Python, Python AI Tutorial, AI Models, Generative AI, Open Source AI, Hugging Face Transformers, PyTorch, Local LLM, LLM Tutorial, AI Python Projects, Gemma 4 Installation, Gemma 4 Setup, UPDATEGADH