Time Series Classification Algorithms
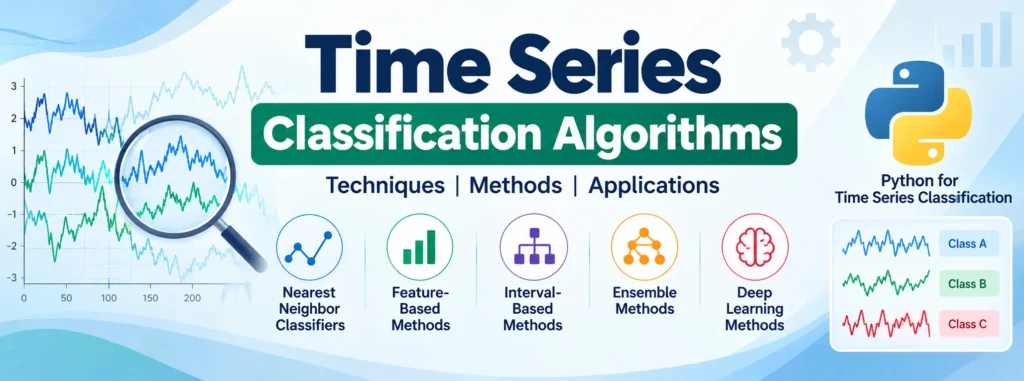
Time series classification is an important task in data science that involves assigning sequential data to predefined classes. It is widely used across industries such as finance, healthcare, weather forecasting, manufacturing, and many others. Since time series data has unique characteristics, especially the importance of sequence order and temporal dependencies, specialized classification algorithms are often required.
In this article, we provide an overview of some of the most prominent time series classification algorithms, along with their working principles, advantages, and limitations.
Table of Contents
Complete Advance AI Topics: Click Here
SQL Tutorial: Click Here
1. Nearest Neighbor Classifiers
Dynamic Time Warping (DTW)
Dynamic Time Warping (DTW) measures the similarity between two time series that may differ in speed or timing. It is particularly useful when two sequences contain similar patterns but those patterns are not perfectly aligned in time.
How DTW Works
- Distance Matrix: Calculates the distance between points in the two time series.
- Cost Matrix: Uses dynamic programming to calculate the minimum cumulative distance.
- Warping Path: Identifies the optimal path between the sequences with the lowest overall cost.
Advantages
- Handles variations in the speed of sequences.
- Accurately matches similar patterns that are misaligned in time.
Disadvantages
- Can be computationally expensive because of its quadratic complexity.
- Performance can depend on parameters such as the warping window.
DTW in k-NN
When combined with k-Nearest Neighbors (k-NN), DTW can be used as the distance measure between a query series and training samples. The class is then determined through majority voting among the nearest neighbors.
Shape-Based Distance (SBD)
Shape-Based Distance (SBD) compares the overall shape of time series rather than relying only on point-by-point alignment.
How SBD Works
- Z-Normalization: The time series is normalized before comparison.
- Cross-Correlation: Similarity is measured while allowing the sequences to shift relative to one another.
- Maximum Correlation: The highest correlation value represents the strongest similarity between the sequences.
Advantages
- Focuses on the overall shape of the series.
- Can be more robust to noise and outliers.
Disadvantages
- May not perform well when exact temporal alignment is important.
- Similarity calculations can still be computationally expensive.
SBD in k-NN
SBD can be used with k-NN to calculate the similarity between time series. The final class is assigned based on majority voting among the closest samples.
2. Feature-Based Methods
Time Series Forest (TSF)
Time Series Forest (TSF) is an ensemble method based on decision trees. It randomly selects intervals from a time series and extracts statistical features from those intervals before constructing the trees.
How It Works
- Random intervals are selected from the time series.
- Statistical features such as mean, standard deviation, and slope are extracted.
- Decision trees are trained using the extracted features.
Shapelet Transform (ST)
Shapelets are discriminative subsequences that can help distinguish between different classes. Shapelet Transform identifies useful subsequences within time series and uses them as features for classification.
Advantages of Feature-Based Methods
- Can be integrated easily with traditional machine learning algorithms.
- Extracts important patterns from time series data in a structured way.
Disadvantages of Feature-Based Methods
- Feature engineering can require considerable time and effort.
- Hand-crafted features may fail to capture complex temporal dependencies.
3. Interval-Based Methods
Time Series Bag of Features (TSBF)
Time Series Bag of Features (TSBF) divides a time series into intervals, extracts features from those intervals, and combines the resulting feature vectors into a bag-of-features representation.
Process
- Interval Selection: The time series is divided into selected intervals.
- Feature Extraction: Statistical features such as mean, standard deviation, skewness, and kurtosis are calculated.
- Bag Creation: Feature vectors generated from different intervals are combined into a collective representation.
- Classification: The resulting features can be provided to classifiers such as SVMs or decision trees.
Pros
- Can capture both local and global patterns.
- Can be applied to relatively large datasets.
Cons
- Performance can be sensitive to parameter selection.
- Extracted features may contain redundant information.
Learned Pattern Similarity (LPS)
Learned Pattern Similarity (LPS) identifies discriminative patterns from the training data and transforms each time series into a similarity-based feature representation.
Pros
- Can generate highly discriminative features.
- Adapts the learned patterns to different datasets.
Cons
- Can require significant computational resources.
- Performance can be sensitive to parameter settings.
4. Ensemble Methods
HIVE-COTE (Hierarchical Vote Collective of Transformation-Based Ensembles)
HIVE-COTE combines multiple classifiers and data transformations to create a powerful ensemble for time series classification.
How It Works
- Combines different classification approaches, including DTW, TSF, Shapelet Transform, and other methods.
- Uses transformations such as Fourier-based representations and shapelet-based representations.
- Applies hierarchical voting to combine predictions from different components.
Pros
- Can achieve high classification accuracy.
- Captures different characteristics and representations of time series data.
Cons
- Has a complex architecture.
- Can require significant computational and memory resources.
Proximity Forest
Proximity Forest is an ensemble of decision trees that uses different proximity measures, such as DTW, Euclidean distance, and SBD, to classify time series.
Pros
- Uses multiple distance measures to capture different types of similarity.
- Can improve classification performance through ensemble learning.
Cons
- Can have high computational requirements.
- Performance may depend on the choice of distance measures.
5. Deep Learning Methods
Recurrent Neural Networks (RNNs)
Recurrent Neural Networks (RNNs) are designed to process sequential data. They use a hidden state to retain information from previous time steps, allowing the network to capture temporal dependencies.
Variants
- LSTM: Long Short-Term Memory networks use gating mechanisms to capture and manage long-term dependencies.
- GRU: Gated Recurrent Units provide a simpler architecture with fewer parameters than LSTMs while still handling sequential dependencies effectively.
Pros
- Effective at learning temporal structures.
- Can handle variable-length sequential inputs.
Cons
- Can be difficult and time-consuming to train.
- May require substantial computational resources.
Convolutional Neural Networks (CNNs)
Convolutional Neural Networks (CNNs) can process time series as one-dimensional signals. Convolutional filters identify local patterns and features within the sequence.
Pros
- Supports efficient parallel computation.
- Effective at identifying local patterns.
Cons
- May be less effective at capturing very long-term dependencies without suitable architectural design.
- Many CNN-based approaches work best with fixed-length inputs.
Hybrid Models (CNN + RNN)
CNN + RNN hybrid models combine convolutional and recurrent architectures to learn both local features and temporal dependencies.
Workflow
- CNNs Extract Features: Convolutional layers identify important local patterns.
- RNNs Capture Dependencies: Recurrent layers process the extracted features across time.
- Final Classification: The learned representation is passed to a classifier to predict the class.
Pros
- Combines local feature extraction with temporal dependency learning.
- Can provide strong performance on complex sequential datasets.
Cons
- Architecture can be more complicated to design and train.
- Can require substantial computational resources.
YT:- DecodeIT
Final Thoughts
Time series classification is a specialized machine learning task that can require different approaches depending on the characteristics of the data and the requirements of the application. Distance-based techniques such as DTW, feature-based approaches such as TSF and Shapelet Transform, ensemble methods such as HIVE-COTE and Proximity Forest, and deep learning architectures such as RNNs and CNNs all offer different strengths and trade-offs.
Understanding these time series classification algorithms helps data scientists and engineers select appropriate techniques and build more effective classification systems for sequential data.
Stay tuned for more insights into data science and machine learning.
Keywords: time series classification python, time series classification example, time series classification GitHub, time series classification algorithms, time series classification machine learning, time series classification deep learning, time series classification transformer, time series classification dataset, time series classification Kaggle, time series classification sklearn